How Anthropic Ran 1,250 AI-Moderated Interviews (2027 Guide)
How Anthropic Interviewer worked, what 1,250 AI-moderated interviews found about the say-do gap, and a playbook to run qualitative research at scale.
Most product teams have more research questions than research hours. Anthropic tested one way around that limit: let an AI run the interviews and keep humans in charge of the plan and the analysis. This guide covers how Anthropic Interviewer worked, what 1,250 interviews revealed, and how a small team can run a version of the same study. At BuildBetter, we work with B2B product teams on the same problem. Customers say one thing in interviews, and their calls, tickets and Slack threads often show something else. Anthropic's study puts a number on that gap and shows how to design around it.
The Story: Anthropic's AI Interviewer Ran 1,250 Interviews While Humans Owned the Plan and the Analysis
On December 4, 2025, Anthropic announced Anthropic Interviewer, a Claude-powered tool that runs detailed interviews automatically at scale and passes the results to human researchers. Its first study interviewed 1,250 professionals: 1,000 from the general workforce, 125 scientists and 125 creatives, all recruited through crowdworker platforms.
The AI ran the conversations. Human researchers reviewed the plan and led the analysis.
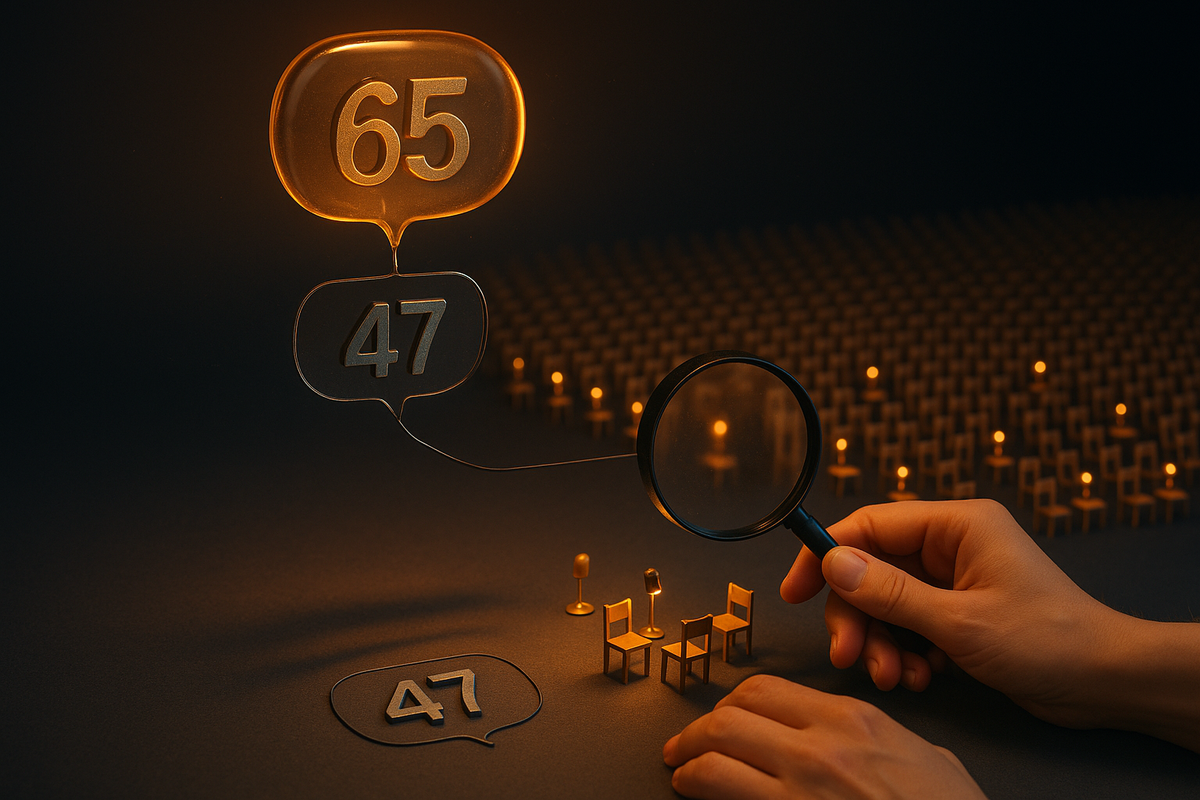
The most quotable finding: participants described their AI use as 65% augmentative, while Anthropic's Economic Index found 47% augmentation in actual Claude conversations. What people say does not always match what they do.
Below you'll find the mechanics, the questions Anthropic had to answer, and how a small team can run its own version in a month.
What Anthropic Actually Did: The Three-Stage Workflow
According to Anthropic's announcement, Anthropic Interviewer runs in three stages: planning, interviewing and analysis, with humans reviewing the plan and leading the analysis.
- Planning: The tool generated an interview rubric and conversation flow from a system prompt that contained the research methodology and hypotheses. Human researchers reviewed and edited the plan before any interviews ran.
- Interviewing: Claude conducted real-time adaptive interviews on Claude.ai. Each lasted about 10 to 15 minutes.
- Analysis: A human researcher worked with the tool on the transcripts. Anthropic also used Clio, its automated analysis tool, to identify themes and measure how often each one appeared.
| Stage | Who leads | Output |
|---|---|---|
| Planning | AI drafts; human researchers review and edit | Interview rubric and conversation flow |
| Interviewing | AI (Claude on Claude.ai) | Adaptive 10–15 minute interview transcripts |
| Analysis | Human researcher, supported by the tool and Clio | Themes, theme frequencies, findings |
The sample was 1,250 professionals (1,000 general workforce, 125 scientists, 125 creatives) recruited through crowdworker platforms. Participants rated the format well: Anthropic reports that 97.6% rated their satisfaction 5 or higher and 99.12% would recommend the interview format.
Anthropic also opened a one-week public pilot at claude.ai/interviewer for existing Free, Pro and Max users. That pilot was time-limited, so don't plan a research program around the tool being available.
What They Found: Key Results From the 1,250 Interviews
The headline result is that people's descriptions of their AI use leaned more toward augmentation than their actual usage did. The supporting figures below all come from the Anthropic Interviewer announcement:
- 86% of the general workforce said AI saves them time (Anthropic).
- 65% of the general workforce were satisfied with AI's role in their work (Anthropic).
- 69% of the general workforce mentioned social stigma around using AI at work (Anthropic).
- 65% augmentative / 35% automative: how participants described their own AI use (Anthropic).
- 47% augmentation / 49% automation: what Anthropic's Economic Index found in actual Claude conversations (Anthropic).
- 79% of scientist interviews named trust and reliability concerns as the primary barrier (Anthropic).
- 91% of scientists wanted more AI assistance in their research (Anthropic).
Two patterns are worth pulling out. First, the gap between 86% saying AI saves time and 65% being satisfied with its role shows that feeling efficient and feeling content are different things. A usage dashboard would show only the first. Second, scientists hold two positions at once: they distrust the output and still want more of it. That tension is exactly what a product team needs to hear before building, and it rarely shows up in a feature-request form.
For context, Anthropic's Economic Index defines augmentation as AI collaborating with a person who stays actively involved by iterating, learning and validating. Automation means AI completing a task with minimal human involvement.
The Questions Anthropic Had to Answer
Before running 1,250 interviews, Anthropic had to settle five design questions that any research team faces when it adds AI moderation.
What can interviews tell us that usage logs can't?
Interviews capture motivation, sentiment and context. The 69% who mentioned stigma around AI at work would never appear in telemetry. Anthropic held one of the richest usage datasets in AI and still ran interviews. See What Are AI-Moderated User Interviews?
Which parts of research should AI run and which should humans own?
AI ran the interviews. Humans reviewed and edited the plan and worked through the analysis. See Human-in-the-Loop AI Research Synthesis.
How do we run hundreds of interviews without a large research team?
Automated, adaptive 10–15 minute interviews on Claude.ai, with participants recruited through crowdworker platforms. See How to Run User Interviews at Scale With AI.
How do we quantify themes across many transcripts?
Clio identified themes and measured how often they appeared, while a human researcher led interpretation. See How Does Anthropic Interviewer Work?
How do we check self-reported behavior against actual behavior?
Compare interview claims (65% augmentation) against observed usage (47% augmentation in the Economic Index). See Self-Reported vs Actual Behavior in User Research.
What Are AI-Moderated User Interviews?
AI-moderated user interviews are research conversations in which an AI model asks the questions and adapts follow-ups in real time, while humans design the study and interpret the results.
In Anthropic's version, Claude ran adaptive interviews of about 10 to 15 minutes on Claude.ai. It followed a rubric and conversation flow that human researchers had already reviewed and edited. The AI improvised within those limits. It did not decide what the study was for.
How it differs from a survey
A survey collects fixed responses to fixed questions. An adaptive AI interviewer can probe: when a participant says "I mostly use it for drafts," it can ask what happens to the draft next. That follow-up is where conversational research earns its keep. It surfaces the workaround, the hesitation or the social pressure that a multiple-choice question flattens.
How it differs from a human-moderated interview
You gain scale and consistency. Every participant gets the same core questions in the same order, and you can run hundreds of sessions in the time a researcher runs a dozen. You give up the moderator's in-the-moment judgment: noticing a pause, reading tone, deciding a tangent is the real story. That trade-off is why Anthropic kept planning and analysis in human hands.
Do this month
- Pick one research question you currently can't answer from analytics.
- Decide whether you need depth (a few human interviews) or breadth (many AI-moderated ones).
- Write down your hypotheses before choosing any tool.
How Does Anthropic Interviewer Work?
Anthropic Interviewer works in three stages: it plans a rubric from a researcher-written system prompt, runs adaptive interviews in real time, and then supports a human researcher in analyzing the transcripts.
Planning
The system prompt contained the research methodology and the hypotheses. From that, the tool generated an interview rubric and conversation flow, which human researchers reviewed and edited. Most of the value in an AI interview study is decided here. A vague brief produces a vague rubric, and a vague rubric produces thousands of shallow transcripts.
Interviewing
Claude conducted real-time adaptive interviews on Claude.ai, each lasting about 10 to 15 minutes. Short sessions are a design choice. They lower the burden on participants, reduce drop-off and make high volume practical.
Analysis
A human researcher worked with the tool on the transcripts. Clio identified themes and measured their frequency, which is how a finding like "69% mentioned social stigma" becomes possible across 1,000 interviews.
Availability
Anthropic ran a one-week public pilot at claude.ai/interviewer for existing Free, Pro and Max users. Treat the tool as a reference design, not a product you can count on.
Do this month
Copy the structure even if you never use the tool. Write a one-page brief with your methodology and hypotheses stated plainly. Have a second person red-line the discussion guide. Keep sessions to roughly 10–15 minutes so you can run more of them.
Can AI Conduct User Research Interviews?
Yes. Anthropic's study shows AI can run adaptive research interviews at scale with high participant satisfaction, as long as humans own the research plan and the interpretation.
The evidence: 97.6% of participants rated their satisfaction 5 or higher, and 99.12% would recommend the format. Read those numbers carefully. They are self-reported, they come from crowdworkers who were paid to participate, and they measure how the interview felt, not whether it produced good insight.
AI is strongest at running consistent, adaptive conversations across a large sample, 1,250 in this case. It doesn't get tired at interview 400, doesn't skip the question it finds awkward and doesn't lead the witness differently on a Friday afternoon.
Humans remain essential at three points:
- Setting hypotheses: deciding what the study is trying to learn.
- Approving the conversation flow: catching leading questions, missing segments and jargon.
- Deciding what themes mean: a theme count is a fact, and its implication for your roadmap is a judgment.
Treat AI moderation as a breadth instrument, not a replacement for depth. Use many short AI-moderated sessions to map the territory and count themes, then use a handful of human-moderated sessions to dig into the surprises.
Do this month
Run a pilot of 20–30 AI-moderated interviews alongside 3–5 human-moderated ones using the same guide. Compare depth, follow-up quality and how many unexpected findings each method produced before you scale.
How to Run User Interviews at Scale With AI
To run user interviews at scale with AI, write a hypothesis-driven brief, have humans approve an AI-generated rubric, run short adaptive interviews with a recruited panel, and use automated theme counting under human review.
Anthropic's version: 1,250 participants recruited through crowdworker platforms, 10–15 minute sessions, and three segments (general workforce, scientists, creatives) so findings could be compared across groups.
Step 1: Define segments up front
Mirror Anthropic's 1,000 / 125 / 125 split: one broad sample for baseline patterns, plus focused subgroups large enough to compare. For a B2B product, that might be a broad sample of active users plus admins and churned accounts.
Step 2: Write the brief
State your methodology and hypotheses explicitly in the system prompt or brief. Writing hypotheses down before fieldwork protects against post-hoc storytelling. When results come back, you'll know which hypotheses were confirmed, which were refuted, and what you didn't anticipate.
Step 3: Human review of the rubric and flow
Have a researcher edit the generated discussion guide before launch. Check for leading questions, double-barreled questions and segment-specific gaps.
Step 4: Recruit and keep sessions short
Recruit through your customer base, an in-app prompt or a research panel. Aim for 10–15 minutes per session.
Step 5: Theme, then validate
Theme the transcripts with automated tooling, then have a researcher check that each theme is defined consistently and that its frequency count is right. "Mentioned in 69% of interviews" carries weight with stakeholders only if the count holds up.
Step 6: Check against behavior
Compare what people said with behavioral data before acting. The next sections cover how.
What to Look for in an AI Interview Tool for Qualitative Research
A good AI interview tool for qualitative research lets humans author and approve the interview plan, adapts follow-ups in real time, exports full transcripts and quantifies themes across them.
Use Anthropic's three stages as your evaluation criteria:
- Plan editing: Can a researcher review and change the rubric and conversation flow before launch?
- Adaptive interviewing: Does the moderator follow up on answers, or just read a script?
- Analysis support: Does it identify themes and report how often they appear?
Add three more: full transcript export, segment tagging, and a way to connect findings to behavioral or operational data.
1. BuildBetter: best for testing interview themes against real customer evidence
BuildBetter is not an AI interviewer. It captures and analyzes real customer conversations, support tickets, Slack threads and surveys, so you can bring interview transcripts into the same place and check whether a theme from 300 interviews also shows up in sales calls and support queues. It applies your taxonomy and severity to each signal individually and turns validated themes into PRDs and tickets.
2. Taguette
A free, open-source tool for highlighting and tagging text documents. It is useful for manually coding a validation sample of transcripts.
3. QualCoder
Free, open-source qualitative data analysis software for coding text, image, audio and video data, with built-in reporting on code frequencies.
4. Whisper
OpenAI's open-source speech recognition model. It is useful for transcribing human-moderated sessions so they can be analyzed next to AI-moderated transcripts.
When another approach fits better
If your main need is running the conversation itself, choose a dedicated AI interview-moderation platform. Those tools are purpose-built for recruiting, moderating and screening at volume.
Self-Reported vs Actual Behavior in User Research
People's self-reported behavior often differs from what they actually do. In Anthropic's study, participants described 65% of their AI use as augmentative, while actual Claude conversations in the Economic Index showed 47% augmentation and 49% automation.
That is an 18-point gap on the core question of the study, and it is the clearest quantified example of the say-do gap you'll find in recent AI research. Interviews reveal motivation and perception. Decisions that rest only on stated behavior can be skewed, because people describe the version of their work they believe in or want others to see.
Anthropic handled this by checking interview claims against its own usage data. It didn't throw out the interviews; it read them alongside the logs. The interviews explained why, and the Economic Index anchored what.
One possible contributing factor, offered as interpretation and not as a finding: 69% of the general workforce mentioned social stigma around AI use at work. If using AI to do a task outright feels less respectable than collaborating with it, people may lean toward describing their use as augmentation. This pattern is well documented as social desirability bias.
Do this month
For every key interview claim, name the behavioral source that would confirm or contradict it:
- Product analytics: does usage match the stated workflow?
- Support tickets: are people hitting the problems they say they don't have?
- Sales and CS call recordings: what do customers say when they aren't being interviewed?
- Internal Slack threads: what does your team hear from accounts every week?
BuildBetter is one example of a platform that puts calls, tickets and Slack in one place so this check takes hours, not weeks.
Human-in-the-Loop AI Research Synthesis: Who Owns What
In human-in-the-loop research synthesis, AI handles volume tasks like running interviews and counting themes, while humans own the hypotheses, approve the plan and interpret the findings.
Anthropic's model followed this split. Humans reviewed and edited the plan, a human researcher worked with the tool on the analysis, and Clio identified and counted themes. Here is that model as a simple ownership table for your own research ops:
| Task | AI leads | Human leads | Human reviews |
|---|---|---|---|
| Hypotheses | ✓ | ||
| Interview rubric and conversation flow | ✓ (drafts) | ✓ (edits and approves) | |
| Interviewing | ✓ | Spot-checks transcripts | |
| Theme detection and counting | ✓ | ✓ | |
| Theme validation | ✓ | ||
| Recommendations | ✓ |
Notice that the AI never owns a decision about meaning. It drafts, it runs and it counts. People decide what the study asks and what the answers imply for the roadmap.
Do this month
Add two mandatory human review gates: one before launch (the plan) and one before sharing (the themes and their counts). Log every edit at both gates. The log gives you an audit trail, helps you improve the next brief and answers the stakeholder who asks, "Who decided this theme was real?"
What to Copy and What Not to Copy
Copy Anthropic's structure and discipline, not its exact setup.
Copy
- The three-stage structure: plan, interview, analyze, with clear owners for each.
- Human ownership of the plan and analysis: AI runs conversations; people decide what they mean.
- Short sessions: 10–15 minutes keeps volume feasible.
- Segmented samples: a broad group plus focused subgroups you can compare.
- Quantified themes: count themes across transcripts, as Anthropic did with Clio, instead of relying on the three most memorable quotes.
- Behavioral validation: check stated behavior against observed behavior before acting.
Don't copy blindly
- The recruitment source: participants came from crowdworker platforms. Your B2B customers, especially senior buyers, may respond very differently to an AI moderator.
- The satisfaction scores: 97.6% and 99.12% are self-reported by paid participants. Don't present them to stakeholders as proof your customers will feel the same.
- The resources: Anthropic had its own model, Claude.ai as the interview surface, Clio for theme analysis and Economic Index data for comparison. Most teams have none of those in-house.
- The scope: the public pilot ran for one week and was limited to existing Free, Pro and Max users.
Where Customer Evidence Fits
Anthropic's finding that what people say (65% augmentation) differs from what they do (47%) makes the case for pairing interviews with real behavioral evidence from customer calls, support tickets and Slack.
Anthropic had the Economic Index to check its interviews against. Most product teams don't have anything like it. They do, however, already hold behavioral evidence: it is spread across call recordings, support queues, CRM notes and internal channels where account managers relay what they hear. The problem is that nobody can search it all at once.
BuildBetter unifies call recordings, Slack, support tickets, surveys and product feedback through 100+ integrations, including Zoom, Slack, Jira, Salesforce, Zendesk, HubSpot and Intercom. Once interview transcripts sit next to that evidence, you can test each theme. If 40% of interviewees say onboarding is easy, do support tickets and CS calls agree? If interviewees rarely mention a competitor, do sales calls say the same? Because internal team activity and external customer feedback live together, you can see both what customers report and what your team is already hearing.
BuildBetter then turns validated themes into deliverables: PRDs, Linear and Jira tickets, and loop-closure emails that tell customers when the thing they asked for has shipped. From customer conversation to shipped decision.
To be clear about the limits: it is not an AI interview moderator, and dedicated user-research repositories have more mature tagging and highlight-reel workflows. Its role is the evidence layer that keeps interview findings honest.
FAQ
What is Anthropic Interviewer?
A Claude-powered tool, announced by Anthropic on December 4, 2025, that runs detailed interviews automatically at scale and passes the results to human researchers for analysis.
How many people did Anthropic interview?
1,250 professionals: 1,000 from the general workforce, 125 scientists and 125 creatives, all recruited through crowdworker platforms.
How long were the AI-moderated interviews?
About 10 to 15 minutes each, conducted on Claude.ai.
How does Anthropic Interviewer work?
In three stages. It generates a rubric and conversation flow from a researcher-written system prompt containing methodology and hypotheses, and humans review and edit it. It then conducts real-time adaptive interviews. Finally, it supports a human researcher in analyzing the transcripts, with Clio identifying themes and measuring their frequency.
Did participants like being interviewed by AI?
97.6% rated their satisfaction 5 or higher, and 99.12% would recommend the format. Both figures are self-reported by crowdworker participants.
What did scientists say about AI?
Trust and reliability concerns were the primary barrier in 79% of scientist interviews, yet 91% wanted more AI assistance in their research.
Why compare interviews with usage data?
Participants described their AI use as 65% augmentative, but Anthropic's Economic Index found 47% augmentation in actual Claude conversations. Stated and actual behavior can diverge, so interview claims should be checked against behavioral evidence.
Sources and Further Reading
- Anthropic, "Anthropic Interviewer" announcement, December 4, 2025: https://www.anthropic.com/news/anthropic-interviewer. This is the source for all study facts and figures, including the Economic Index comparison.
- Wikipedia, Qualitative research: https://en.wikipedia.org/wiki/Qualitative_research
- Wikipedia, Human-in-the-loop: https://en.wikipedia.org/wiki/Human-in-the-loop
- Wikipedia, Social desirability bias: https://en.wikipedia.org/wiki/Social_desirability_bias. Background on why self-reports can diverge from behavior.
Make Churn Optional
Interviews tell you what customers believe. Calls, tickets and Slack show you what they actually do. Put both in one place, test every theme against real evidence and ship the PRDs and tickets that follow.