How Airbnb Used LLMs to Migrate 3,500 Test Files in 6 Weeks
How Airbnb migrated 3,500 Enzyme tests to React Testing Library with LLMs in 6 weeks: validation gates, retry loops, context, and steps to copy.
Airbnb's engineering team moved nearly 3,500 React component test files from Enzyme to React Testing Library in about six weeks. Its own manual estimate for the same work was about 1.5 years of engineering time. In Airbnb's engineering post, the company calls this its first large-scale, LLM-driven code migration. We wrote this breakdown at BuildBetter for engineering and product leaders who are deciding whether to run a migration like this, and what to do with the capacity it frees. The Airbnb post page shows no publication date. InfoQ covered the project in an article dated March 28, 2025.
The short version: Airbnb paired validation-gated steps with brute-force retries and rich file context, and that turned a migration it had avoided for years into a six-week project.
The guide covers the pipeline mechanics, the five questions Airbnb had to answer, six practical how-to sections, the limits of the case study, and where customer evidence fits once the work is done.
The Story: Airbnb Moved Nearly 3,500 Test Files in About 6 Weeks Instead of 1.5 Years
Airbnb finished a test framework migration in about six weeks that it had estimated would take 1.5 years of manual engineering time. The scope was nearly 3,500 React component test files written against Enzyme, a testing utility that many React teams adopted years ago and that has become harder to maintain alongside modern React. The target was React Testing Library (RTL), which tests components through the interface a user sees rather than through component internals.
Per the Airbnb post, this was the company's first large-scale code migration driven by large language models. That framing is important. Airbnb was not polishing an established internal platform. It was testing whether LLMs could take on a class of work that engineering teams usually defer because it is repetitive, wide, and hard to schedule against feature work.
The answer, in this case, was yes. The result did not come from a clever model choice, though. Airbnb never names the model in its post. The result came from three design decisions:
- Validation gates: every step had to pass existing automated checks before a file moved on.
- Retries with feedback: failed steps were retried with the actual errors and the latest version of the file.
- Deliberate context: prompts included the related files the model needed to get the change right.
The rest of this guide takes each of those apart and turns them into steps your team can run.
What Airbnb Actually Did: The Mechanics of the Pipeline
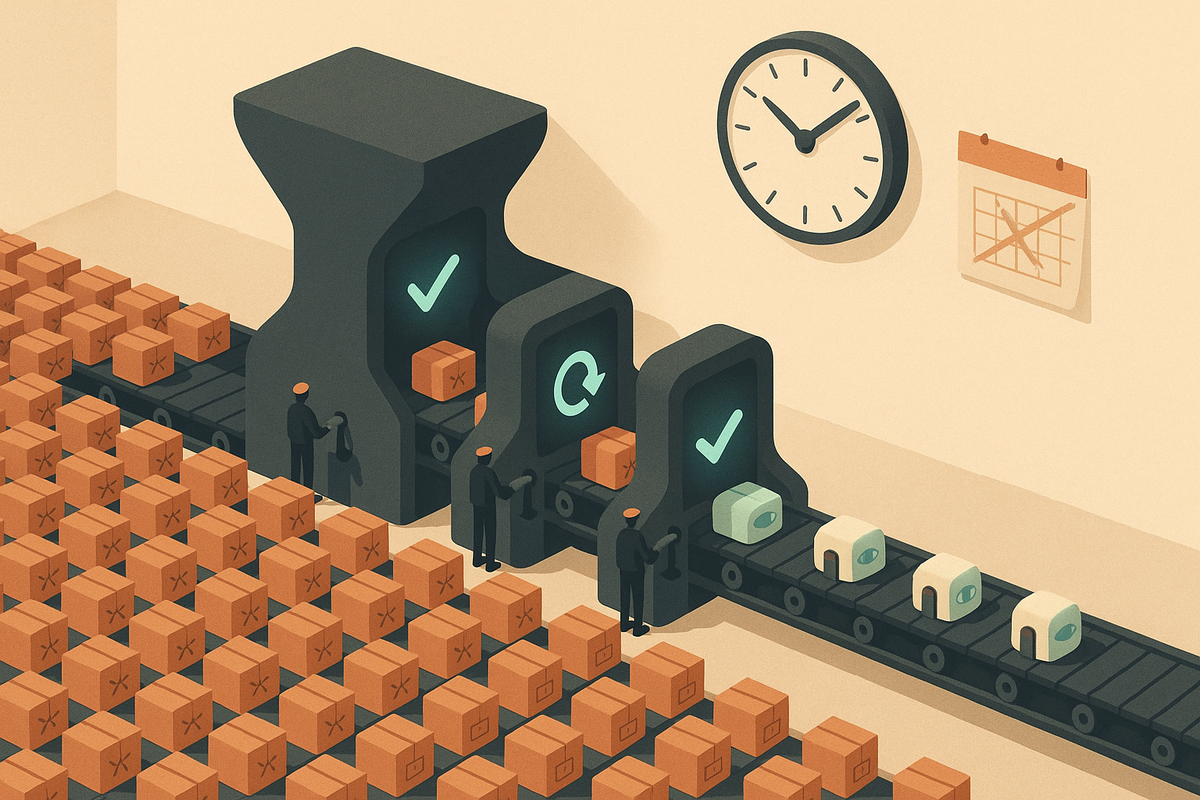
Airbnb built a per-file state machine in which each test file passed through four ordered steps, and a file advanced only after the current step passed validation. According to the Airbnb post, the states were:
- Enzyme refactor: rewrite the test from Enzyme APIs to React Testing Library.
- Fix Jest: get the rewritten test passing under Jest.
- Fix lint and tsc: clear ESLint and TypeScript compiler errors.
- Mark complete: the file is done.
When a step failed, the pipeline retried it with a dynamic prompt. That prompt contained the validation errors and the latest version of the file, not the original. Most files finished within 10 attempts. Some long-tail files were retried 50 to 100 times. Prompts grew to between 40,000 and 100,000 tokens and included as many as 50 related files.
Charles Covey-Brandt, a staff software engineer at Airbnb, summed up the design to InfoQ: “This step-based approach provided a solid foundation for our automation pipeline.”
The results came in three phases, all reported in the Airbnb post:
- The first bulk run migrated 75% of target files in four hours.
- A “sample, tune, sweep” loop over four days raised completion to 97%.
- Engineers fixed the remaining files by hand over about another week.
Flow diagram, described in text: Four boxes sit in a row from left to right: “Enzyme refactor” → “Fix Jest” → “Fix lint + tsc” → “Complete.” Each of the first three boxes has a loop arrow that points back to itself, labeled “fail: retry with errors + latest file.” A forward arrow between boxes is labeled “pass validation.” Files that never pass drop out to a “manual fix” queue below the row.
The Questions Airbnb Had to Answer
Before it could trust the pipeline, Airbnb had to settle five practical questions. Each answer below is attributed to the Airbnb post or to InfoQ.
Can an LLM handle a codebase-wide migration we've avoided for years?
In Airbnb's case, yes. The migration took about six weeks against a manual estimate of 1.5 years of engineering time, according to the Airbnb post. The estimate and the result are both self-reported.
How do we validate each AI-generated change automatically?
Gate every step on checks that already exist. Airbnb used Jest, lint, and tsc as the pass conditions for its pipeline steps, so no file advanced on the strength of model output alone (Airbnb post).
Is it better to tune prompts or to retry with feedback?
Airbnb leaned on retries. In its words: “we found the most effective route to improve outcomes was simply brute force.” Retries carried the errors and the current file, so each attempt built on the last one.
What context does the model need to get a file right?
The right related files. Airbnb wrote that “the main success driver we saw was choosing the right related files.” Prompts carried up to 50 of them.
Where do humans step in for the long tail?
After automation reached 97%, Airbnb engineers fixed the remaining files manually over about another week (Airbnb post). Human work was planned for, not treated as a failure.
How Did Airbnb Migrate from Enzyme to React Testing Library with LLMs?
Airbnb ran each Enzyme test file through an automated, step-by-step LLM pipeline in which every step had to pass validation before the next began, and failed steps were retried with error feedback until the file passed. Most of the nearly 3,500 files were migrated automatically. Engineers finished the long tail.
Per the Airbnb post, the sequence was: the four-step state machine, dynamic retry prompts, large related-file context, a bulk run, the sample-tune-sweep loop, and manual cleanup.
Why this migration is hard
Enzyme tests often reach into component internals. They use shallow rendering, inspect state and props, and call instance methods. React Testing Library takes the opposite approach: you call render, query the DOM the way a user would with queries like getByRole, and simulate interaction with user-event. Shallow rendering vs render is a change in testing philosophy, not just a syntax swap. A find-and-replace codemod cannot rewrite a test that asserts on internal state into one that asserts on visible behavior. That is the gap an LLM can fill, and also why automated validation is essential.
How a smaller team can do this month
These are our recommendations, not Airbnb practices:
- Inventory your Enzyme test files and group them by complexity: shallow-only, mount with simple assertions, and heavy use of instance or state access.
- Pick 20 to 50 representative files as a pilot, drawn from each group.
- Define “done” as the file passing Jest, lint, and type checks. Nothing else counts.
- Run the pilot, record the failure types, and scale to the full set only after you understand them.
Can You Use LLMs for Large-Scale Code Migration?
Yes, if you have objective, automated checks that tell you whether each changed file is correct. Airbnb's result depended on validation gates, not on trusting model output. Without machine-checkable correctness, the same pipeline would produce unverified code faster.
Airbnb treated the migration as thousands of small, independently validated file-level jobs rather than one giant change (Airbnb post). That structure is what made large-scale code migration with AI tractable. Any single file could fail without blocking the others.
Fit checklist
Score a candidate migration against these four criteria:
- Repetitive across many files. The same kind of transformation applies hundreds or thousands of times.
- Machine-checkable success. Tests, a type checker, and a linter can tell you whether a file is right.
- Independent files. Each file can be migrated and validated on its own.
- A manual fallback. Engineers are available to finish the long tail.
Poor-fit signals
- Little or no test coverage, so “passes” means nothing.
- Changes that need product judgment, such as deciding what a feature should do.
- Cross-file refactors that cannot be validated one file at a time.
This month
List the migrations your team has deferred: framework upgrades, deprecated API removals, logging library swaps. Score each against the checklist. Start with the one that has the strongest automated validation, even if it is not the most urgent. A first win on a well-validated migration builds the tooling and trust for harder ones.
How Do You Automate Code Migrations with AI? A Step-Based Approach
Break the migration into ordered steps, give each step its own validation, let a file advance only when the current step passes, retry failures automatically, and send what's left to humans.
Airbnb's state machine migration pipeline ran Enzyme refactor → fix Jest → fix lint and tsc → mark complete. As Covey-Brandt told InfoQ, “This step-based approach provided a solid foundation for our automation pipeline.”
Why steps help
This is our analysis, not an Airbnb claim. Steps shrink each prompt's task: “make this Jest test pass” is easier for a model than “rewrite, fix, and clean up this file.” Each step produces a clear error signal from one validator. Progress is resumable, because a file that cleared Jest yesterday does not need to repeat that step today. Files can also run in parallel.
A minimal implementation
- Track each file's state in a simple table or JSON file.
- Write one script per step that calls the model, writes the output, and runs that step's validator.
- Make steps idempotent, so rerunning a step on a file that already passed is safe and cheap.
- Log every attempt and error per file, for tuning and for the human queue.
A state record can be this small:
{
  "file": "src/components/Listing/__tests__/Listing.test.tsx",
  "state": "fix_jest",
  "attempts": { "refactor": 1, "fix_jest": 4 },
  "last_error": "TestingLibraryElementError: Unable to find role 'button'"
}
Optional: deterministic codemods first
Deterministic tools such as jscodeshift or ts-morph can handle mechanical parts, such as import rewrites or renaming wrapper utilities, before the LLM step. That reduces what the model has to do. Airbnb did not report doing this. It is our suggestion.
How Should an LLM Retry Loop Use Validation Errors?
On each retry, send the model the exact validation errors and the latest version of the file, not the original. Airbnb found that brute-force retrying with this feedback improved outcomes more effectively than other approaches it tried.
Airbnb's dynamic prompts contained the errors and the current file version. Most files finished within 10 attempts. Some long-tail files took 50 to 100 attempts (Airbnb post). In Airbnb's words: “we found the most effective route to improve outcomes was simply brute force.”
Retrying against the latest file is the detail that makes this work. If every attempt starts from the original Enzyme test, the model repeats the same mistakes. If it starts from the partly fixed version plus the remaining errors, it makes incremental progress. Cheap automated iteration plus a strict validator often beats long rounds of prompt engineering.
This month
- Capture full error output from Jest, the linter, and tsc. Do not truncate stack traces the model may need.
- Template the prompt as: task + current file + errors + context.
- Set a per-file attempt cap for each step.
- Route capped files to a human queue with their full error history attached, so the engineer sees what the model already tried.
A simple template:
TASK: Make this React Testing Library test pass under Jest.
CURRENT FILE: {latest_file_contents}
ERRORS: {jest_output}
CONTEXT: {component_source} {migrated_examples} {test_utils}
Your attempt caps and costs will differ from Airbnb's. Airbnb did not publish cost figures, so budget from your own pilot data rather than from this case study.
What Are AI Codemod Pipeline Best Practices?
Validate every step automatically, retry with feedback, give the model the right related files, sample before you sweep, and plan a human pass for the long tail.
Airbnb's numbers show how each phase contributed:
| Phase | Completion | Duration | Source |
|---|---|---|---|
| First bulk run | 75% of target files | 4 hours | Airbnb post |
| Sample, tune, sweep loop | 97% | 4 days | Airbnb post |
| Manual cleanup | Remainder (~3%, roughly 100 files by our arithmetic) | About another week | Airbnb post (percentage); file count derived |
Sample, tune, sweep in plain terms
Sample a set of the files that failed. Look for patterns: the same unsupported Enzyme API, a shared test helper the model misreads, a missing type. Tune the prompt or the context to address the pattern. Then sweep all remaining failures again. Repeat. Tuning on failure clusters added about 22 percentage points in Airbnb's run.
Recommendations for your team
- Run a bulk pass early. It finds the easy majority and shows you what the hard cases look like.
- Tune on clusters, not individual files. One fix to the context selector can clear dozens of failures.
- Keep humans reviewing merged changes. Passing checks proves the test runs, not that it tests the right behavior.
- Track percent complete daily. A flattening curve tells you when to stop tuning and start manual cleanup.
How Much Context Should You Give an LLM for Code Changes?
More than most teams expect, chosen carefully. Airbnb's prompts reached 40,000 to 100,000 tokens with up to 50 related files, and the company named related-file choice as its main success driver: “the main success driver we saw was choosing the right related files.”
Airbnb did not name a model in its post. In its account, context selection mattered more than model selection.
Related files to consider
These are our recommendations, not Airbnb's published list:
- The component under test.
- Its direct imports, especially child components the test renders.
- Sibling tests in the same directory that have already been migrated to RTL.
- Shared test utilities, custom render wrappers, and providers.
- Type definitions for props and context values.
Already-migrated sibling tests are especially useful because they show the model your team's RTL conventions: which queries you prefer, how you wrap providers, how you mock data.
This month
- Build a related-file selector from your import graph. ts-morph can resolve imports and walk the tree.
- Run an A/B comparison on your pilot set: pass rate with and without migrated example tests in the prompt.
- Check your model's context window limits before you scale up the file count.
Caution: relevance beats volume. Irrelevant files add noise and can lower pass rates. Measure pass rate each time you change the LLM context window for code changes, and keep only what helps.
What to Copy and What Not to Copy from Airbnb's Migration
Copy the structure, not the timeline. The pipeline design transfers well. The six-week number may not.
Copy
- Validation-gated steps, so no file advances on model output alone.
- Retry loops that send the latest file plus its errors.
- Deliberate related-file selection.
- The sample-tune-sweep cadence after an early bulk run.
Don't assume
Do not assume your timeline will match. The 1.5-year estimate and the six-week result are self-reported by Airbnb and depend on its test coverage, internal tooling, and engineering staff. A team with weaker coverage or a smaller platform group will see different numbers.
Not disclosed in the sources
The Airbnb post and InfoQ coverage do not disclose the specific model, the compute cost, or details of the code review process. We are not going to guess at them, and you should be skeptical of any write-up that does.
Date caveat
The Airbnb post shows no publication date. InfoQ's coverage is dated March 28, 2025.
Limits
- This was a test-file migration with strong automated checks. Migrations that touch production logic carry more risk and need stronger human review.
- The long tail is real. The last 3% still took about a week of manual work. Staff for it.
Where Customer Evidence Fits: Deciding Where Reclaimed Engineering Time Goes
Migrations like this free engineering time, and customer evidence should decide where that time goes next. Otherwise the hours saved get absorbed by whatever is loudest in the backlog rather than by the problems customers are raising.
To be clear, this is not part of Airbnb's story. It is our recommendation for engineering managers and product leaders who are about to get weeks or months of capacity back.
The risk is predictable. A migration finishes early, and the freed sprint fills with internal requests, half-scoped ideas, or the last feature a senior stakeholder mentioned. The customer problems driving churn and support volume stay where they were.
BuildBetter addresses this by putting internal and external evidence in one place. It brings together your team's own conversations, including call recordings and Slack threads, with external sources like support tickets, surveys, and product feedback through 100+ integrations. Each piece of feedback is analyzed individually for severity and business impact, so teams can see which customer problems deserve the reclaimed capacity.
BuildBetter also turns that evidence into deliverables: PRDs and Jira or Linear tickets with the customer context attached. That shortens the path from a customer conversation to a shipped decision.
Practical steps before the migration ends
- Pull the top recurring customer issues from calls and support tickets over the last quarter.
- Rank them by frequency and revenue impact.
- Draft the first post-migration sprint around the top three, with tickets ready before the last file merges.
Tools for Running an LLM Migration and Using the Time It Frees
This is a categorized toolkit, not a ranking of migration tools. Each entry notes which job it serves.
| Tool | Category | Role in the workflow |
|---|---|---|
| BuildBetter | Customer evidence | Decides where reclaimed engineering time goes |
| jscodeshift | Deterministic codemod | Mechanical JavaScript transforms before LLM steps |
| ts-morph | TypeScript AST | Related-file discovery and structured edits |
| Jest, ESLint, tsc | Validation gates | Pass/fail checks for each pipeline step |
| React Testing Library | Migration target | The testing library files move to |
1. BuildBetter — Best for deciding where reclaimed engineering time goes
BuildBetter is not a code migration tool. Its job in this workflow comes after the migration: unifying calls, Slack, tickets, and surveys so you can point freed capacity at the customer problems with the most evidence and revenue behind them, then ship PRDs and tickets from that evidence. Honest weaknesses: dedicated research-repository workflows and enterprise survey distribution at scale are not its core strength.
2. jscodeshift
A toolkit for deterministic JavaScript codemods. Use it for mechanical transformations, such as import paths and wrapper renames, before the LLM step, so the model handles only the parts that need judgment.
3. ts-morph
A library for TypeScript AST manipulation. Useful for walking import graphs to pick related files for the prompt and for precise structured edits.
4. Jest, ESLint, and the TypeScript compiler (tsc)
The validation gates that mirror Airbnb's pipeline steps. Jest confirms the test runs and passes. ESLint and tsc confirm it meets your code standards and types. These checks are what make Jest test migration automation trustworthy.
5. React Testing Library
The migration target. The official docs cover render, query priorities like getByRole, and pairing with user-event. Feed the relevant guidance to your model as context.
FAQ: Airbnb's LLM Test Migration
How long did Airbnb's LLM test migration take?
About six weeks, compared with Airbnb's manual estimate of about 1.5 years of engineering time (Airbnb post).
How many files did Airbnb migrate?
Nearly 3,500 React component test files, moved from Enzyme to React Testing Library.
What percentage did the LLM pipeline migrate automatically?
75% in the first four-hour bulk run, then 97% after a four-day sample-tune-sweep loop. Engineers fixed the rest manually over about another week.
What were the steps in Airbnb's pipeline?
A per-file state machine with four states: Enzyme refactor, fix Jest, fix lint and tsc, then mark complete. A file advanced only after the current step passed validation.
How many retries did files need?
Most finished within 10 attempts. Some long-tail files were retried 50 to 100 times. Each retry included the validation errors and the latest file version.
How big were the prompts?
Between 40,000 and 100,000 tokens, including as many as 50 related files.
Can smaller teams replicate this?
Yes, with scaled-down steps: a pilot set, automated validation gates, a retry loop with errors, and a human queue for the long tail. Results will vary with test coverage and tooling.
What should teams do with the time saved?
Point it at customer-raised problems. Tools like BuildBetter surface those problems from calls, Slack, and support tickets, and turn them into PRDs and tickets.
Sources and Further Reading
- Airbnb Engineering, Enzyme to React Testing Library LLM migration post: https://airbnb.tech/?p=366 (page shows no publication date)
- InfoQ coverage, dated March 28, 2025: https://www.infoq.com/news/2025/03/airbnb-llm-test-migration/
- React Testing Library official docs: https://testing-library.com/docs/react-testing-library/intro/
- Enzyme on GitHub: https://github.com/enzymejs/enzyme
- Jest official site: https://jestjs.io/
- Wikipedia, Large language model: https://en.wikipedia.org/wiki/Large_language_model
Make churn optional.
Your next migration might hand your team back months of engineering time. Spend it on the problems your customers keep raising. BuildBetter connects every call, Slack thread, support ticket, and survey, and turns that evidence into PRDs and tickets your team can ship.