How Intercom Doubled R&D Output With AI Agents (2027 Guide)
How Intercom hit 2x R&D output with Claude Code: merged PRs metric, auto-approved PRs, a 267-skill plugin repo, token spend, and steps to copy it.
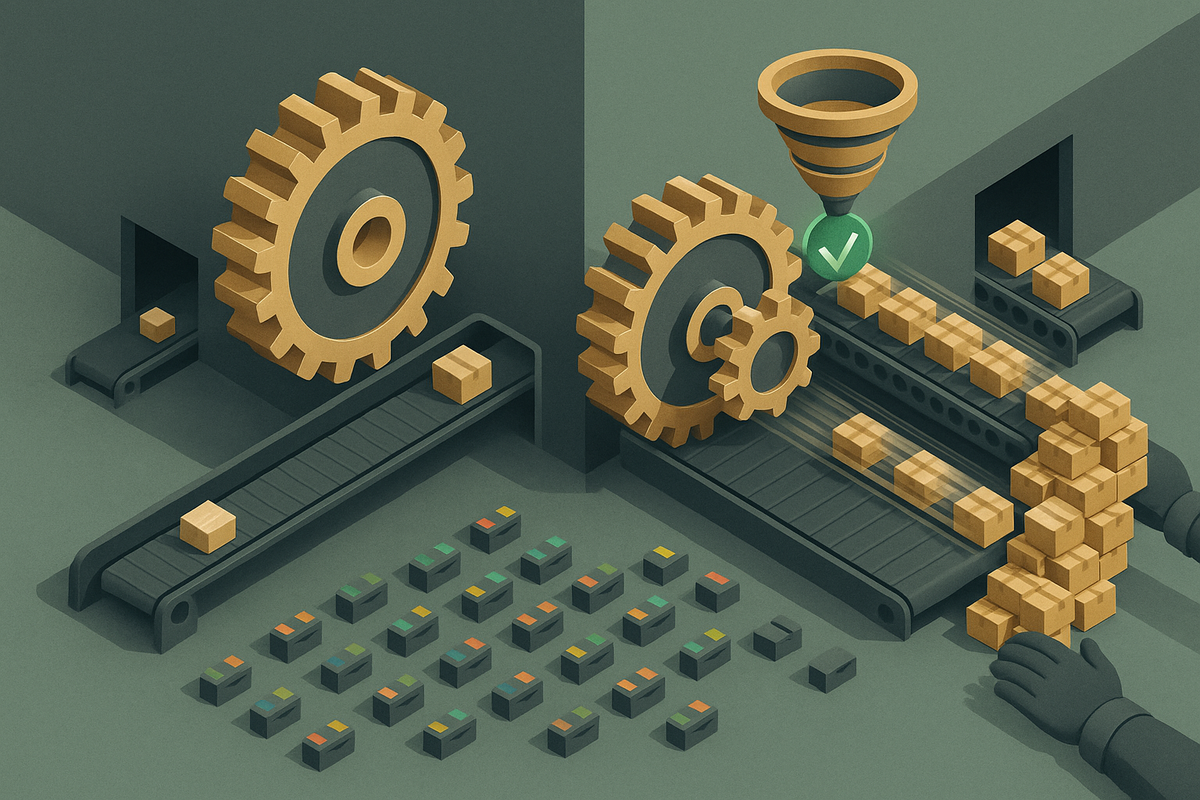
Intercom set a public goal to double R&D productivity in 12 months with AI coding agents. It hit the goal early and then published the numbers. This guide covers what Intercom measured, how it ran auto-approved pull requests, how it shared Claude Code skills across hundreds of people, and what it saw in token spend. Each section ends with steps you can run this month. The last sections cover a problem that 2x output creates: if engineers ship twice as fast, deciding what to build becomes the constraint. That is where customer evidence from calls, tickets, and Slack matters, and where BuildBetter fits. Unless marked otherwise, every figure below comes from Intercom's own report.
The Story: Intercom Publicly Committed to 2x R&D Output, Then Published the Scoreboard
Intercom doubled its R&D output in about nine months using agent-first engineering, according to a report its CTO published on April 16, 2026. In "2x - nine months later: We did it" on Intercom's Fin Ideas blog, Darragh Curran wrote that the company had reached its 12-month goal of doubling R&D productivity "with time to spare." Over 16 months, output is up roughly 3x, and the author says Intercom has not hit a plateau yet.
The post presents the effort as a company-wide change of direction, not a tooling experiment:
"All technical work is becoming agent-first. This is the top priority for R&D."
Two points before the details:
- Every number is self-reported. The figures come from Intercom's own post and have not been independently audited. Publishing a goal creates accountability, and it also creates pressure to report good results.
- The headline is throughput, not cycle time. The post also mentions idea-to-shipped speed gains, but the title and body report them inconsistently. This guide does not treat them as a headline result. The caveats section covers this.
Intercom's report is useful because it goes beyond the result. It explains the metric, the adoption targets, the auto-approval rules, the shared tooling, and the quality data, including one quality signal that got worse. That makes it one of the most detailed public accounts of scaling AI coding agents across a full R&D organization.
What Intercom Actually Did: The Mechanics Behind Agent-First Engineering
Intercom combined one throughput metric, aggressive adoption targets, staged autonomous merges, a shared skills repo, and public quality guardrails. All figures below are attributed to Curran's April 16, 2026 post.
- The metric: merged PRs divided by total R&D headcount. The denominator counts every R&D role, from IC engineers to the VP of product design. The author calls the metric imperfect and pairs it with other measures.
- Adoption target: more than 80% of PRs agent-driven within six weeks, later raised to 95%. The current figure is 93.6%.
- Autonomous merges: 19.2% of merged PRs are auto-approved with no human reviewer. Intercom started with low-risk changes such as feature flag cleanups and small bug fixes. In the first four weeks, 497 PRs went fully autonomous.
- Auto-approval speed: auto-approved PRs merge in a median of 14.6 minutes, compared with 75.8 minutes org-wide. 86% of them are 20 lines or fewer.
- Shared tooling: a dedicated "team-2x" runs a shared, auto-updating Claude Code plugin repo with 267 skills and 153 contributors (31% of R&D).
- Adoption outside engineering: nearly 1,100 of 1,305 staff were peak active Claude Code users. More than 600 of them work outside R&D.
- Quality and reliability: the defect backlog is down 54% since the start of the year, and all critical and high defects are closed. Downtime caused by breaking code changes fell 35% over 11 months while deployments doubled.
- One negative signal: a structural code-quality score declined as the share of AI-written code grew. A recent five-week streak of net positive quality "may not last," according to the author.
The Six Questions Intercom Had to Answer
Any engineering org scaling AI coding agents has to answer the same six questions Intercom faced. Short answers are below. Each links to a longer section.
How do we measure whether AI is actually making R&D more productive?
Intercom used merged PRs per total R&D headcount and paired it with quality and reliability measures. See the measurement section.
What target do we set, and do we commit to it publicly?
Intercom set 2x in 12 months and announced it publicly. A public target gave the effort a deadline and an audience. See how Intercom did it.
Which PRs can merge without a human reviewer, and how do we start safely?
Low-risk categories came first: flag cleanups and small bug fixes. Small diffs made up most of the volume. See the auto-approval section.
How do we share prompts, skills, and agent setups across hundreds of engineers?
Intercom used one shared, auto-updating plugin repo owned by team-2x and open to anyone who wanted to contribute. See the skills marketplace section.
How do we keep quality and uptime from slipping as AI-written code grows?
Intercom tracked the defect backlog, downtime caused by code changes, and a structural quality score, and published all three, including the one that declined. See the metric section.
How much token spend is worth it per engineer?
Most high-output engineers at Intercom spend over $1k/month, but spend alone does not predict output. See the token spend section.
How Do You Measure Engineering Productivity With AI Coding Agents?
Choose one simple, org-wide throughput metric, such as merged PRs per total R&D headcount, and pair it with quality and reliability guardrails so the number can't be raised by shipping worse code. Intercom followed this pattern, and it works without a large developer-productivity team.
The denominator is the important choice. Intercom divides merged PRs by everyone in R&D: IC engineers, engineering managers, designers, and the VP of product design. That changes what the metric rewards. If you count only engineers, the number tracks individual coding speed. If you count everyone, it tracks how much the whole org can ship, including a designer fixing a UI bug with an agent or a PM shipping a copy change without waiting in an engineering queue.
The author calls the metric imperfect, and that is fair. PR counts ignore size and value. A slightly flawed metric that everyone understands and checks weekly is still better than an elaborate framework nobody looks at. You can keep DORA metrics for delivery health and use this one for throughput.
Do it this month
- Set a baseline. Pull 6-12 months of merged PR counts from your Git host so you can see your starting trend.
- Define the denominator. Include everyone in R&D, not only engineers. Write the definition down so it stays the same.
- Pick two guardrails. Defect backlog and incidents caused by code changes are good starting points.
- Publish and review. Put the dashboard where all of R&D can see it and review it in a weekly meeting.
How Did Intercom Double Engineering Output With Claude Code?
Intercom made agent-first work the top R&D priority, set aggressive adoption targets, allowed low-risk PRs to merge autonomously, and centralized skills in a shared Claude Code plugin repo. By its own report, it reached 2x inside its 12-month window.
The order of the steps matters as much as the steps:
- Public goal. Announce 2x in 12 months so the deadline is real.
- Adoption target. Require more than 80% of PRs to be agent-driven within six weeks, then raise the bar to 95%.
- Shared skills repo. Give team-2x ownership of a plugin repo so useful setups spread across the org instead of staying on one laptop.
- Auto-approval for low-risk changes. Remove the review queue for flag cleanups and small fixes.
- Quality guardrails. Track defects, change-caused downtime, and structural quality, and publish them.
The reported results are 93.6% of PRs agent-driven, 19.2% auto-approved, and 3x output over 16 months, all self-reported.
Do it this month (without Intercom's resources)
- Name one owner for agent enablement, even if the role is part-time. Without an owner, adoption stalls.
- Set a six-week adoption target you can measure from PR metadata. A commit trailer or PR label for agent-driven work is enough.
- Start a shared skills repo with 5-10 skills based on your most frequent tasks. A small repo that people use is worth more than a large one they ignore.
Is Merged PRs per Engineer a Good Productivity Metric in the AI Era?
Merged PRs per engineer is a useful directional metric, but it is imperfect on its own because PR size and value vary widely. Pair it with quality, reliability, and customer-outcome measures. Intercom's author says the same thing.
The weaknesses are predictable. Goodhart's law applies: once merged PRs becomes a target, teams can split one change into five small PRs and the chart improves while nothing else does. The metric also says nothing about whether the shipped work mattered to a customer. Ten merged PRs that fix the wrong problem count the same as ten that reduce churn.
Intercom addressed this by reporting three counterweights next to throughput: the defect backlog (down 54%), downtime caused by breaking changes (down 35% while deployments doubled), and a structural code-quality score. It also reported that the quality score declined as AI-written code grew. Publishing a guardrail that moved the wrong way makes the rest of the report more credible.
Do it this month
- Add a PR-size distribution chart next to the throughput chart. If the median PR shrinks sharply while throughput rises, look into why.
- Tag PRs by type (feature, fix, cleanup) so you can see when the mix shifts. A jump driven entirely by cleanups is a different result from one driven by features.
- Review the fastest-moving teams qualitatively each month. Read a sample of their PRs and ask what customer problem each one solved.
Should AI-Generated Pull Requests Be Auto-Approved?
Some AI-generated pull requests can be auto-approved safely if you start with narrow, low-risk categories and small diffs. At Intercom, 19.2% of merged PRs are auto-approved with no human reviewer, and 86% of those are 20 lines or fewer.
Intercom began with feature flag cleanups and small bug fixes. These changes are easy to verify mechanically and easy to revert. In the first four weeks, 497 PRs went fully autonomous. The speed gain is large: a median of 14.6 minutes to merge versus 75.8 minutes across the org, about 5x faster.
That gap points to a more general lesson. Once agents write most of the code, code review latency often becomes the main bottleneck. Much of the 75.8 minutes is time spent waiting for a reviewer.
On risk: change-caused downtime fell 35% over 11 months while deployments doubled (self-reported). That is a correlation. It does not prove auto-approval is safe in every codebase. Expand eligibility one category at a time based on incident data.
Do it this month
- Write an allowlist of eligible categories: flag removal, lint and formatting fixes, copy changes, minor dependency bumps, and small bug fixes with tests. Exclude auth, payments, data migrations, security-sensitive paths, and infrastructure.
- Cap diff size (for example, 20 lines) and require passing CI.
- Run in shadow mode for two weeks, logging which PRs would have auto-merged without merging them.
- Turn it on for one repo and review incidents every week.
How Do You Roll Out Claude Code to a 500-Person Engineering Org?
Run the rollout as an org-wide program with a dedicated owning team, a time-boxed adoption target, and shared tooling, not as an optional tool individuals can try. Intercom's rollout succeeded because leadership made it the top R&D priority.
Intercom's headcount is described two ways in the post. One section refers to roughly 500 people building and operating the product, and another refers to "473 people in R&D." Both describe an organization of about 500 people, so the playbook applies to orgs of that size.
The more surprising result is how far adoption spread outside engineering. Nearly 1,100 of Intercom's 1,305 staff were peak active Claude Code users, and more than 600 of them were outside R&D. Once shared skills existed, people in other functions began using agents for technical work too. This is also why the all-of-R&D denominator matters: it captures contributions from people who don't have "engineer" in their title.
Do it this month (for a smaller org)
- Run a two-week pilot with one volunteer team per function: backend, frontend, platform, design.
- Publish a "first five tasks" playbook that lists the specific tasks new users should try first, such as writing tests for an existing module or removing a stale flag.
- Track weekly active users and the agent-driven PR share on the same dashboard as throughput.
- Expand to non-engineering roles once the shared skills repo exists, so new users start with tested setups.
What Does an Agent-First Engineering Team Structure Look Like?
In an agent-first team, agents are the default way technical work gets done, and humans focus on review, judgment, and deciding what to build. In practice this requires a dedicated enablement team, shared skills that many people contribute to, and a plan for uneven adoption.
Intercom's structure has three visible parts. First, team-2x owns enablement and maintains the shared plugin repo. Second, contributions are spread widely: 153 people, 31% of R&D, have contributed skills. Enablement is not limited to a small platform team. Third, output is concentrated. The top 5% of contributors produce more than 6x the median contributor's output.
That concentration affects how you plan. Expect adoption to be uneven, and don't treat the median as a failure. Your top agent users have already figured out workflows that others haven't. Make teaching part of their role instead of an unpaid side task.
The human role changes too. When an agent writes most of the code, engineers spend more time on specification, review, system design, and choosing which problem to solve next. That last part depends on information that is not in the codebase.
Do it this month
- Assign enablement ownership to a named team or person.
- Write a contributor guide that explains how to propose, test, and publish a skill.
- Pair your top agent users with lower adopters for regular working sessions.
How Do You Build a Claude Code Skills Marketplace for Your Team?
Put skills, prompts, and agent setups in one shared, versioned repo that auto-updates on engineers' machines, with a clear owner and open contributions. Intercom's version is an auto-updating Claude Code plugin repo with 267 skills and 153 contributors.
A skill packages instructions, typically in a SKILL.md file with supporting scripts, so an agent can perform a recurring task the way your team wants it done. Plugins bundle skills, commands, and configuration, and a plugin marketplace distributes them. The mechanics are covered in the Claude Code plugins documentation and the Agent Skills documentation.
Auto-updating is the part teams most often skip. If engineers have to pull updates manually, their setups drift apart and an improvement to one skill reaches only a few people. When the repo updates automatically, a fix one engineer makes on Tuesday is on every machine by Wednesday.
Do it this month
- Create the repo and seed it with skills for your most frequent tasks, such as flag cleanup, test scaffolding, and migration patterns.
- Add a README template for each skill covering what it does, when to use it, known limits, and the owner.
- Automate distribution so engineers always have the latest version.
- Track usage and remove unused skills. A smaller set of skills that work well is better than a large catalog nobody trusts.
How Much Should You Spend on AI Coding Tokens per Engineer?
There is no universal benchmark for AI coding token spend per engineer. At Intercom, most high-output engineers spend over $1k/month on tokens, but high spend does not guarantee high output. Measure output per dollar instead of capping spend without data.
Read the $1k/month figure carefully. It is a pattern Intercom observed among its high performers, not a recommended budget. Some people at Intercom spend heavily and produce little, which shows that spending more tokens does not by itself make anyone more productive. Spend reflects how someone works. It does not measure value.
A hard cap carries a specific risk. Because output is so concentrated (the top 5% produce more than 6x the median), a flat cap mostly restricts your most productive people. The money saved is small compared with the output you lose.
Do it this month
- Track spend per person alongside merged PRs and your guardrail metrics.
- Look for high-spend, low-output outliers and coach them. Common causes are long, unfocused sessions, missing skills, or vague task specifications.
- Avoid hard caps that restrict top contributors. Use alerts for unusual spikes instead.
What to Copy From Intercom, and What Not to Copy
Copy Intercom's structure. Be cautious about its numbers. The approach transfers well. The specific figures may not apply to your organization.
Copy
- A public, time-boxed goal
- A simple metric with an all-of-R&D denominator
- Staged auto-approval that starts with low-risk diffs
- A shared skills repo with a dedicated owner
- Quality guardrails tracked and published, including the ones that look bad
Don't copy blindly
- Self-reported data. Intercom published every number itself, and none were independently audited.
- Inconsistent headcount. The post gives roughly 500 in one place and 473 in R&D in another.
- Unreconciled cycle-time claims. The title and body report idea-to-shipped improvement differently. Treat cycle-time gains as unconfirmed.
- Declining structural quality. The score fell as AI-written code grew, and the author says the recent improvement streak may not last.
- Different starting conditions. Intercom builds an AI product. Regulated or legacy-heavy codebases may adopt agents more slowly.
- Throughput is not value. Doubling PRs matters only if the work solves real customer problems.
Where Customer Evidence Fits When Agents Double Shipping Speed
When agents double how fast you ship, deciding what to build becomes the bottleneck. If engineering capacity doubles but the input stays the same (a backlog groomed from memory, a few loud requests, a roadmap set last quarter), the extra capacity goes into work nobody is sure customers need.
Customer calls, support tickets, and Slack threads show what customers actually need. They tell you which bug is causing churn at a $200k account, which feature request comes up in a third of discovery calls, and which workaround your CS team keeps explaining. Without that information, 2x output means shipping the wrong things faster.
This section is separate from Intercom's story. Intercom did not use or reference BuildBetter. The workflow below is our recommendation for keeping agent-first output tied to customer needs.
BuildBetter's MCP server gives the coding agent access to that customer evidence. When an engineer or agent picks up a ticket, it can query the calls, signals, and accounts behind it, see the customer's exact words, and build with that context instead of guessing from a one-line ticket title.
A practical workflow
- Customer conversation: a call, ticket, or Slack thread is captured automatically.
- Synthesized evidence: feedback is turned into structured signals with severity and business impact.
- PRD or ticket: generated with linked evidence, then created in Linear or Jira through Tickets.
- Agent-driven PR: the coding agent queries the customer context through MCP while it builds.
The customer context stays attached at every step, so a reviewer can trace any PR back to the customer problem it addresses.
Tools for an Agent-First Workflow That Stays Customer-Grounded
An agent-first workflow needs four layers: customer evidence, shared skills, a standard protocol connecting them, and merge controls.
| Tool | Role in the workflow | Best for |
|---|---|---|
| 1. BuildBetter | Customer evidence layer, exposed to agents via MCP | Building from real customer problems |
| 2. Claude Code plugins and skills | Shared, versioned agent setups | Spreading good workflows across teams |
| 3. Model Context Protocol | Open standard for connecting agents to data | Connecting agents to external systems |
| 4. Git host branch protection and auto-merge | Merge controls | Staged, allowlisted auto-approval |
1. BuildBetter: Best for customer-grounded agent workflows
BuildBetter combines internal sources (calls, Slack) and external feedback (support tickets, surveys) through 100+ integrations and makes all of it available to coding agents through an MCP server. Each piece of feedback is analyzed individually for severity and business impact and categorized with your own taxonomy. Agents get structured evidence instead of keyword matches. Limits: it is not built for enterprise-scale survey distribution or for dedicated research-repository tagging workflows.
2. Claude Code plugins and skills
This is the mechanism Intercom used for its 267-skill shared repo. Skills package recurring tasks, and a plugin marketplace distributes them across the org.
3. Model Context Protocol (MCP)
The open standard for connecting AI agents to external data sources and tools. It lets an agent query customer data, docs, and internal systems without custom integration work for each source.
4. Your Git host's branch protection and auto-merge rules
Required CI checks, path-based rules, and auto-merge settings are how you enforce an allowlist and a diff-size cap for autonomous merges.
FAQ
Did Intercom really double engineering output?
According to Darragh Curran's April 16, 2026 post, yes. Intercom reached 2x within its 12-month goal and reports 3x over 16 months. The figures are self-reported and have not been independently audited.
What metric did Intercom use to measure productivity?
Merged PRs divided by total R&D headcount, which includes non-engineers such as designers and product leaders. The author calls the metric imperfect and pairs it with quality and reliability measures.
What percentage of Intercom's PRs are written by AI agents?
93.6% are agent-driven. The target started at 80% within six weeks and was later raised to 95%.
Is it safe to auto-approve AI-generated pull requests?
It can be, for narrow, low-risk categories with small diffs and passing CI. Intercom auto-approves 19.2% of merged PRs, 86% of those are 20 lines or fewer, and it started with flag cleanups and small bug fixes. Begin with an allowlist, a diff cap, and shadow mode, then review incidents weekly.
What kinds of PRs should be auto-approved first?
Changes that can be verified mechanically and reverted easily: feature-flag removal, small bug fixes with tests, lint and formatting fixes, copy changes, and minor dependency bumps. Exclude auth, payments, data migrations, security-sensitive paths, and infrastructure until your incident data supports expanding.
Did code quality suffer?
Partly. A structural quality score declined as AI-written code grew. Over the same period, the defect backlog fell 54% and change-caused downtime fell 35% (self-reported).
How do I make sure faster shipping targets the right problems?
Feed customer evidence from calls, tickets, and Slack into planning and into the agent itself. BuildBetter's MCP server is one way to do this, so the agent can see the customer context behind each ticket.
Sources and Further Reading
- Darragh Curran, "2x - nine months later: We did it" (April 16, 2026)
- Model Context Protocol official site
- Claude Code plugins documentation
- Wikipedia, Code review
- Wikipedia, Feature toggle
- BuildBetter: customer evidence for product and engineering teams
Ship Twice as Fast, on the Right Problems
AI coding agents increase how much your team can ship. BuildBetter helps make sure that output goes toward the problems your customers raise. It captures every call, ticket, and Slack thread, turns them into evidence with severity and business impact, and gives your coding agents that context through MCP so each PR can be traced back to a real customer.