How to Read AI Chat Logs for Unfinished Customer Work (2026)
A hand-run method to classify AI assistant chats as resolved, partial, unresolved, or unclear, and turn unfinished customer work into roadmap input.
Most teams that ship an AI assistant measure the assistant. Few measure the customer's outcome. This guide gives you a hand-run method for reading AI chat logs to find the work customers could not finish. It is drawn from Ship First by Spencer Shulem, founder of BuildBetter, and it ends with a worked example, a reporting checklist, and guidance on when tools like BuildBetter Chat are worth adding. You can start with a spreadsheet this afternoon.
What Reading Chats for Unfinished Work Means
Reading chats for unfinished work means reviewing AI assistant conversations to decide whether the customer's requested work actually got done. Your product has an AI assistant. The team tracks thumbs-up rate, and maybe failed tool calls. Nobody reads what people were trying to do when the chat ended.
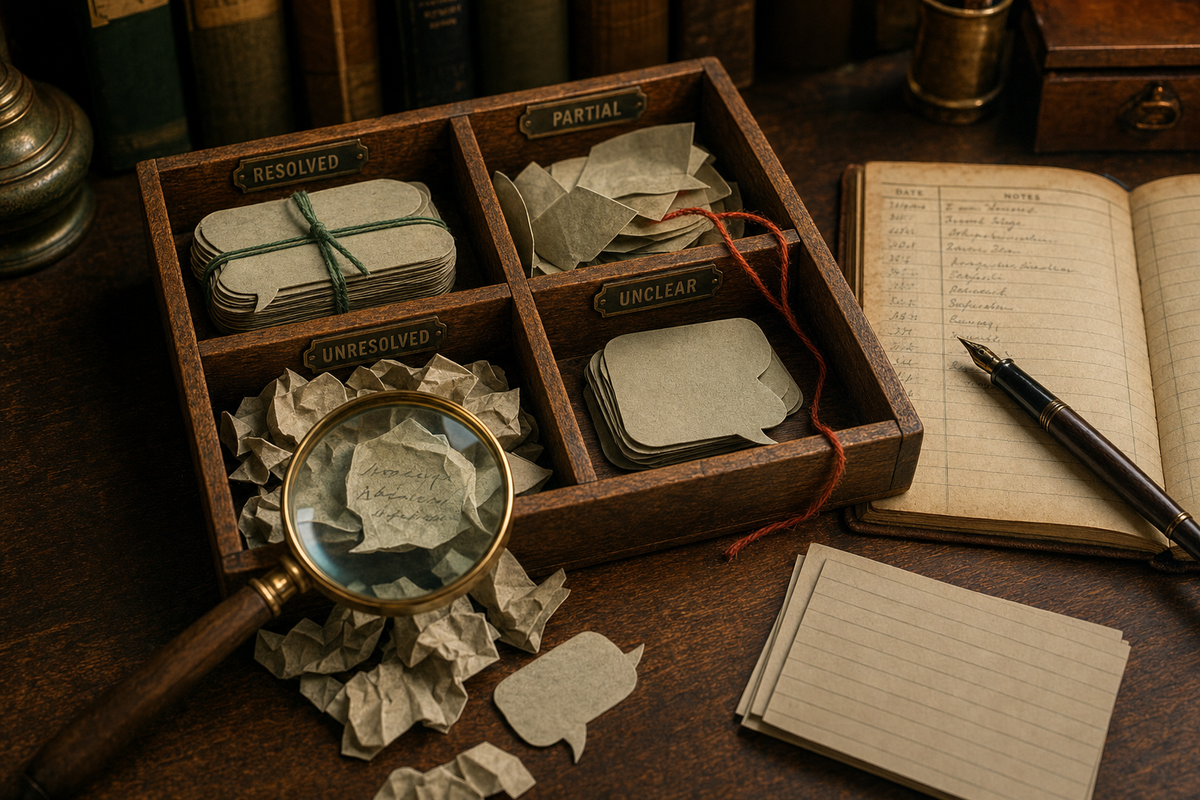
The method classifies each chat as resolved, partially resolved, unresolved, or unclear, and keeps evidence for each label. Whatever remains undone becomes product input. One question anchors every review: did the customer get the issue resolved? Ratings, tool calls, chat length, and sentiment are secondary evidence for answering it.
Why chat logs are a new research source
People bring expectations from general-purpose assistants into your product's chat box. They assume the agent can find information and take action. Their requests show what they expect to accomplish inside your product, including jobs you have not enabled yet. A support ticket tells you something broke. A chat request tells you what the customer thought the product should already do.
Spencer Shulem gives a direct illustration from BuildBetter. Customers ask the company's agent, Bob, about a call they had yesterday, what people on their team are doing, or whether it can update a changelog. Each request marks a spot where user expectations meet the tools, permissions, and capabilities the product actually provides. Some of those requests land on supported features. Others land on a gap, and the gap is the roadmap input.
Why AI Chat Logs Are Hard to Read (and What Breaks)
AI chat logs are hard to read because a conversation can look successful at every technical layer while the customer's job stays undone. Four problems cause most misreadings.
- Clean traces hide incomplete work. Every tool call can return 200 with no timeouts, and the requested job can still be unfinished. Failed calls and timeouts are engineering problems. Unfinished work is a product problem. They need separate tracking.
- Competent-sounding answers hide partial failure. LLM output is written to sound finished. Two examples from the book: the agent locates the right call but fails to answer the question about it, or it produces changelog text when the customer asked it to update the changelog itself.
- Chat endings are ambiguous. People leave because they got the answer, or because they see no point asking again. A missing "thank you" proves neither.
- Reason and outcome get blended. A label of "unresolved" tells you nothing about whether to change the product, the instructions, the retrieval, or the permission messaging.
Which AI assistant metrics mislead
- Thumbs-up rate covers only the few who rate, and it rewards tone over completion. A friendly draft can earn a thumbs-up even when the task never happened.
- Tool-call success rate measures activity, not answers.
- Conversation length or "chat ended" counts read silence as success.
- A single blended resolution rate hides the partially resolved and unclear groups.
- Adoption percentages without denominators hide where people dropped out.
The book gives an illustrative denominator example (not BuildBetter data): 8 accounts requested something, 6 got access, 4 encountered the relevant job, and 3 completed it. Those are four different denominators. Reporting "75 percent adoption" uses only the last two steps and conceals the access gap. Measured against requesters, completion is 37.5 percent.
How this differs from LLM observability and evals
Observability tracks latency, errors, and cost. Evals score answers against prepared test cases. Reading for unfinished work asks whether a real customer's real job got done. You need all three, but only the last one tells you what to build next.
The Method: Classify Every Chat by Customer Outcome
The method is a seven-step manual review that sorts each chat by outcome, records the reason separately, and turns clusters of unfinished jobs into decisions. It comes from Ship First: How to Build Self-Improving Products by Spencer Shulem, a short companion to Customer-Led Development. It runs entirely by hand in a spreadsheet, with no tooling required.
Step 1: Pull a sample and write down the request
Take a consecutive sample of chats. For each one, write a single line describing what the customer was trying to accomplish, in their terms, before you read the assistant's response. This is the most important habit in the method. Recording the goal first keeps a fluent answer from anchoring your judgment. Include thumbs-down reactions and explicit feedback, but do not limit the sample to them.
Step 2: Classify the outcome
| Outcome | What it means | Evidence to retain |
|---|---|---|
| Resolved | The answer or resulting action supports completion of the requested work. | The answer or action that completed the job. |
| Partially resolved | Some requested work was completed. | What was done and what remains. |
| Unresolved | The requested outcome was not delivered. | The reason, where known. |
| Unclear | The available evidence cannot settle the outcome. | The targeted follow-up chosen. |
Step 3: Settle ambiguous endings with evidence, not mood
Check four things: the answer itself, whether the requested action actually happened, the customer's subsequent behavior where available, and any later complaint or repeat request. If those do not settle it, keep the "unclear" label and pick a targeted follow-up. Do not guess. "Unclear" is an honest label, not a reviewer failure.
Step 4: Separate the reason from the outcome
Add a second column with a short, fixed list of reasons, each mapped to a type of fix:
- Missing capability leads to a product change.
- Confusing answer or retrieval gap leads to better instructions, prompts, or knowledge sources.
- Missing permissions means the agent should explain what it can do and how an authorized person can help.
- Other or unknown stays visible so it does not get forced into a bucket.
A limitation can stay a limitation while its explanation becomes much more useful.
Step 5: Keep the evidence
Store the quote or excerpt, what remained undone, the reason, and the follow-up chosen, right beside the label. Anyone should be able to audit a classification later without rereading the full transcript.
Step 6: Group unfinished jobs and decide
Cluster partially resolved and unresolved chats by the job left undone, not by keyword. For each cluster, decide whether to improve the explanation, the product, or both. Reread the underlying conversations before you commit. Partially resolved chats tend to be the richest input: the customer showed clear intent, the agent got partway, and the gap points straight at a missing capability.
Step 7: Close the loop and re-measure
When the change ships, tell the customers who asked. (See how to close the customer feedback loop automatically.) Then compare similar requests before and after the change, and watch whether the same customers need to ask again.
What to do with privacy-sensitive logs
This is general practice, not from the book. Read only the minimum needed. Redact personal data before sharing excerpts. Restrict who can access raw logs, and set a retention limit for the evidence you keep. Follow your privacy policy and applicable law, such as GDPR. When sharing outside the review group, classify with excerpts, not full transcripts.
Don't forget your website or presales agent
A website agent that answers prospects from docs, sales calls, and examples produces discovery material. Unanswered questions show missing information, or capabilities prospects expected to find. Run the same four-category review on those chats.
Worked Example: 200 Chats Classified by Hand
This is an illustrative example, not BuildBetter data.
In this example, a dashboard reading "82% positive" turned out to describe a product where fewer than half of chats fully resolved the customer's request.
Setup. A B2B product's in-app assistant. A PM and a CS lead reviewed 200 consecutive chats from two weeks in a shared spreadsheet. The work took about four hours, split across the two of them.
Starting signal. 44 of the 200 chats were rated (22 percent), and 36 got thumbs-up. The dashboard showed "82% positive," which said nothing about the other 156 chats.
Classification result.
| Outcome | Chats | Share |
|---|---|---|
| Resolved | 96 | 48% |
| Partially resolved | 38 | 19% |
| Unresolved | 41 | 20.5% |
| Unclear | 25 | 12.5% |
Reasons across the 79 partial or unresolved chats: 31 missing capability (39 percent), 27 confusing answer or retrieval gap (34 percent), 12 permissions (15 percent), and 9 other or unknown (11 percent). About 61 percent of unfinished chats would not be fixed by building a new feature.
The cluster that mattered. 19 chats asked the assistant to update a record directly. The assistant drafted the text instead, and the customer had to paste it in themselves. All 19 were classed as partially resolved, and the retained evidence showed exactly what remained: the write itself.
Decision. The next release adds a write action for that record, gated by permission checks. Retrieval fixes for the 27 confusing-answer chats go to the instructions backlog, where most ship in days. The permissions copy gets rewritten so the agent explains what it can do and who can help.
Why not the louder request. A runner-up cluster of 14 chats asked about exporting results into a presentation. It appeared often, but 9 of the 14 were unclear: the team could not tell whether customers wanted a file, a share link, or a summary. Instead of a build, it got a targeted follow-up. The PM asked 5 requesters directly.
Follow-through. The team notifies the 19 requesters at release, then compares similar "update the record" requests over the next two weeks and tracks repeat asks from the same accounts. The report uses separate denominators: requested, got access, encountered the job, completed it.
The inflation trap in numbers. Moving the 25 unclear chats into "resolved" would lift resolution from 48 percent to 60.5 percent with no extra work completed. The book's rule: a rise in apparent resolution deserves investigation if it comes from reclassifying ambiguous chats.
How to Report Chat Outcomes Without Inflating Resolution
Honest reporting keeps all four outcomes visible and ties every change in the mix to evidence a second reviewer can check. Use these rules:
- Report all four categories separately. Never collapse resolved, partially resolved, unresolved, and unclear into one rate.
- Retain the evidence behind each label so a second reviewer can audit shifts in the mix.
- Compare like with like. Measure similar requests before and after a change, not all chats against all chats. A new feature can shift the request mix and distort a blended number.
- Track repeat asks. If the same customers need to ask again, the earlier "resolved" labels were wrong. Correct them.
- Keep account-level and user-level counts separate. One power user asking 12 times is not 12 accounts with the need.
- Measure quality beside speed. Track regressions, rework, and support burden alongside resolution, so a faster agent that creates cleanup work does not look like progress.
- Watch the request mix. Are customers still asking you to fix the existing experience, or asking you to extend it? A shift toward extension requests is a sign the basics now work.
A stable or shrinking unclear rate, paired with targeted follow-ups, is healthier than a resolution rate that climbs because unclear chats were quietly moved.
Common Mistakes When Reading AI Chat Logs
Most chat review mistakes come from treating an absence of complaint as evidence of completion. Watch for these eight:
- Reading only thumbs-down chats. You miss the silent partial resolutions, which hold the most unfinished work.
- Treating clean tool-call traces as success. The calls worked. The job didn't get done.
- Labeling a silent exit as resolved. Silence is evidence of nothing. Use "unclear" and a follow-up.
- Reclassifying unclear chats to hit a target. This inflates resolution without completing any work.
- Skipping the reason column. Without it, every unresolved chat looks like a feature request, when many are instruction, retrieval, or permission-explanation fixes.
- Clustering by keyword instead of by unfinished job. "Changelog" chats can hide three different jobs: find an entry, draft an entry, and publish one.
- Shipping without notifying requesters, then reading low usage as low demand. The people who asked never learned the change existed.
- Pasting raw transcripts with personal data into shared docs or external tools.
When You Need Tooling (and Which Tools Help)
The manual method works well up to roughly 200 to 300 chats per review cycle with two reviewers. Past that, or once you need to join chats with calls, tickets, and Slack threads to settle unclear outcomes, hand review stops keeping pace. Good tooling should surface partial and unresolved candidates, attach evidence, cluster by unfinished job, and connect clusters to tickets. Humans should keep the final classification.
1. BuildBetter: best for settling outcomes across every customer source
BuildBetter Chat lets you ask questions across your assistant transcripts alongside every call, support ticket, Slack thread, and survey, pulled in through 100+ integrations. That matters for Step 3: you can check whether an "unclear" chat was followed by a complaint, a repeat request, or a mention on a later call, with citations back to the source conversation. Chat is permissions-aware, so reviewers only see what they are allowed to see, and it offers local and cloud LLM options for teams with privacy constraints. BuildBetter also turns clusters into Linear or Jira tickets, PRDs, and loop-closure emails to the customers who asked. Caveat: teams that need a dedicated research-repository workflow with highlight reels may want a specialized repository alongside it.
2. Langfuse
Open-source LLM tracing. Useful for pairing transcripts with tool-call traces, but it does not classify customer outcomes for you.
3. PostHog session replay
Shows what a user did after a chat ended, which covers the "subsequent behavior" check for ambiguous endings.
4. A shared spreadsheet with a fixed schema
Columns for request, outcome, reason, evidence, and follow-up. Still the best place to start.
FAQ: Reading AI Assistant Chats
What are the four outcome categories for AI chat review?
Resolved, partially resolved, unresolved, and unclear. Resolved means the answer or action supports completion of the requested work. Partially resolved means some work was done, and you record what remains. Unresolved means the outcome was not delivered, and you keep the reason if known. Unclear means the evidence can't settle it, so you choose a targeted follow-up.
Is thumbs-up rate a good measure of an AI assistant?
No. It covers only the minority who rate, often well under a quarter of chats, and it reflects tone and politeness more than completion. A friendly answer that drafts text instead of doing the task can still get a thumbs-up. Measure whether the requested work got done.
Why isn't tool-call success rate enough?
Tool-call success measures activity, not answers. Every call can succeed while the agent fetches the right data but never answers the question, or returns text when the customer wanted an action. Track tool errors for engineering, and track customer outcomes separately.
How do you tell if a customer left a chat satisfied?
Check four things: the answer itself, whether the requested action actually happened, the customer's subsequent behavior (for example, session replay or product events), and any later complaint or repeat request. If these don't settle it, label the chat unclear and follow up. Never infer satisfaction from silence.
How do you avoid inflating your AI resolution rate?
Report all four categories separately, keep the evidence behind every label, compare similar requests before and after a change, track repeat asks, and investigate any rise in resolution that comes from reclassifying ambiguous chats rather than from completed work.
How many chats should you review?
Start with a consecutive sample of about 200 per cycle, which is enough to see recurring unfinished jobs. Move to tool-assisted triage when volume or cross-source checks outgrow manual review.
Should a missing capability always become a feature?
No. Separate the reason from the outcome. Some gaps need a product change, some need better instructions or retrieval, and some need the agent to explain the limitation and who can help.
Sources and Further Reading
- Spencer Shulem, Ship First: How to Build Self-Improving Products, chapters "Read chats for unfinished work" and "Measure the answer rather than the activity."
- PostHog docs, How to watch recordings.
- Ryan Singer, Shape Up, Chapter 8: The Betting Table, on deciding which unfinished work to bet on.
- Wikipedia, General Data Protection Regulation.
- Wikipedia, Conversation analysis.
Make churn optional.
Every partially resolved chat is a customer who told you exactly what they expected your product to do. BuildBetter puts those chats next to your calls, tickets, and Slack threads, so you can settle unclear outcomes, cluster the unfinished jobs, and ship the fix with the evidence attached. Then it tells the customers who asked.
Make churn optional. Book a demo.
Get Ship First
This method comes from Ship First: How to Build Self-Improving Products by Spencer Shulem: 24 short chapters on going from a customer request to a working release. Get the free PDF or EPUB, or read it on Kindle.