How to Measure Whether a Feature Solved the Problem (2026 Guide)
A five-step method to measure if a feature solved the problem: timed intervals, five denominators, quality, and honest small-sample reporting.
A feature shipped. The dashboard says 75 percent adoption. Someone in the review asks, "75 percent of whom?" and nobody can answer. This guide from the BuildBetter team gives product managers, CS leads and founders a method for answering that question honestly. It covers who asked for the feature, who actually got it, who used it, and whether it did the job they needed done. The whole method runs in a spreadsheet.
What It Means to Measure Whether a Feature Solved the Problem
Measuring whether a feature solved the problem means tracking whether the customers who had the problem got access, met the job, completed it with the feature, and came back the next time the job occurred. Every count is reported with its denominator stated.
The core principle is simple: measure the answer, not the activity. Pull requests, merges and deploys show building activity. Completed customer jobs show whether the answer worked. These are different kinds of numbers, and only the second kind tells you whether a customer's problem went away.
Josh Seiden's Outcomes Over Output (2019) defines an outcome as "a change in human behavior that drives business results." Output metrics count what the team produced:
- Pull requests merged
- Deploys
- Story points completed
- Features shipped
Outcome metrics count changes in what customers do: jobs completed, tasks finished faster, fewer support contacts, repeat use at the next opportunity.
This distinction matters because a feature can ship, show usage on a dashboard, and still leave the original requester's problem unsolved. The person who asked may never have received access. The usage might come from a different segment entirely. The requester might have tried it once, hit a format bug and gone back to their old workaround. Activity metrics cannot show any of this. Only a requester-level view of outcomes can.
Measuring the answer is also how you find out whether your judgment holds up. If you never check whether shipped features solved the problems they were meant to solve, you can't tell whether your prioritization is improving.
Why Feature Measurement Breaks: The Failure Modes
Feature measurement usually breaks because teams report numbers that sound like evidence without stating what they count or what they compare against. Five failure modes show up repeatedly.
- Activity gets read as value. A pull request is not a fixed unit. It can be a feature, a bug fix, a dependency update or one slice of a larger change. Creating a PR is different from merging it, and merging is different from deploying. Deploying is different again from customer availability when feature flags, staged rollouts or plan gating apply. A PR count needs explaining before it can support any argument about customer value.
- Denominators stay hidden. "75 percent" can mean three of four accounts that met the job. It can also hide that only six of eight requesters ever got access.
- Account counts and user counts get mixed. One enthusiastic power user at one account can make adoption look broad when it is narrow.
- Speed gets reported without quality. Regressions, rework and support burden don't appear on a release-velocity chart.
- Claims outrun evidence. Requester usage gets presented as proof of retention. Before-and-after charts get presented as proof of cause.
The research points the same way. Pendo's 2019 Feature Adoption Report, based on anonymized data from 615 subscriptions, found that 80 percent of features in the average product were rarely or never used, and that 12 percent of features generated 80 percent of average daily usage. Treat that carefully. Features were customer-defined tags, so "feature" meant different things across products. Daily-volume measures also favor high-frequency features. A rarely used feature may serve an occasional but important job, so expected frequency has to be part of any judgment.
Ron Kohavi and colleagues reported in Online Controlled Experiments at Large Scale (2013) that only about one third of ideas tested at Microsoft improved the metrics they were designed to improve. If well-resourced teams with strong intuition are wrong two times out of three, you should keep checking your assumptions after release rather than assume success when the feature ships.
The Method: Measure the Answer in Five Steps
The method below measures a shipped feature in five steps: timing, cohort, quality, evidence and support outcomes. It comes from Ship First: How to Build Self-Improving Products by Spencer Shulem, a short companion to Customer-Led Development. Shulem writes that teams should track pull requests separately from deployments and customer outcomes, so they can see how changes in building capacity alter what customers actually receive. Faster building that does not increase completed customer jobs is not progress.
The five steps:
- Time the path from request to first completed job.
- Build the requester cohort and state every denominator.
- Put quality beside speed.
- Match each claim to the evidence it needs.
- Measure support and chat improvements by outcome class.
None of this requires special tooling. One row per requesting account, one column per timestamp and stage, and a notes column for evidence will carry you through your first several releases. Tooling becomes useful later, when rebuilding the requester list by hand turns into the bottleneck.
Step 1: Time the Path From Request to First Completed Job
The customer's clock starts when they ask, not when you release, so measure four intervals from the original request onward. Each interval needs a start timestamp and an end timestamp.
- Request to available release. From the date the customer asked to the date the feature was actually usable by that account. Use usable, not deployed.
- Availability to notification. From availability to the date that specific requester was told.
- Notification to first completed job. From notification to the first time the account finished the task using the feature.
- First use to enough evidence for a decision. From first use to the point where you can decide whether to keep, fix or remove the feature.
Starting the clock at release hides most of the wait the customer actually experienced. A team that reports "shipped in 4 days" may be describing a request that sat for 60 days before anyone picked it up.
The notification interval is usually the hidden delay. Engineering finishes, the changelog goes out, and the people who asked never find out. A feature nobody was told about cannot be adopted, and low uptake then gets misread as low demand. If you need a process for this, see how to close the loop with customers when you ship a feature.
Record the date each requester was notified individually. A changelog publication date is not enough, because it tells you the information existed, not that the requester saw it.
Step 2: Build the Requester Cohort and State Every Denominator
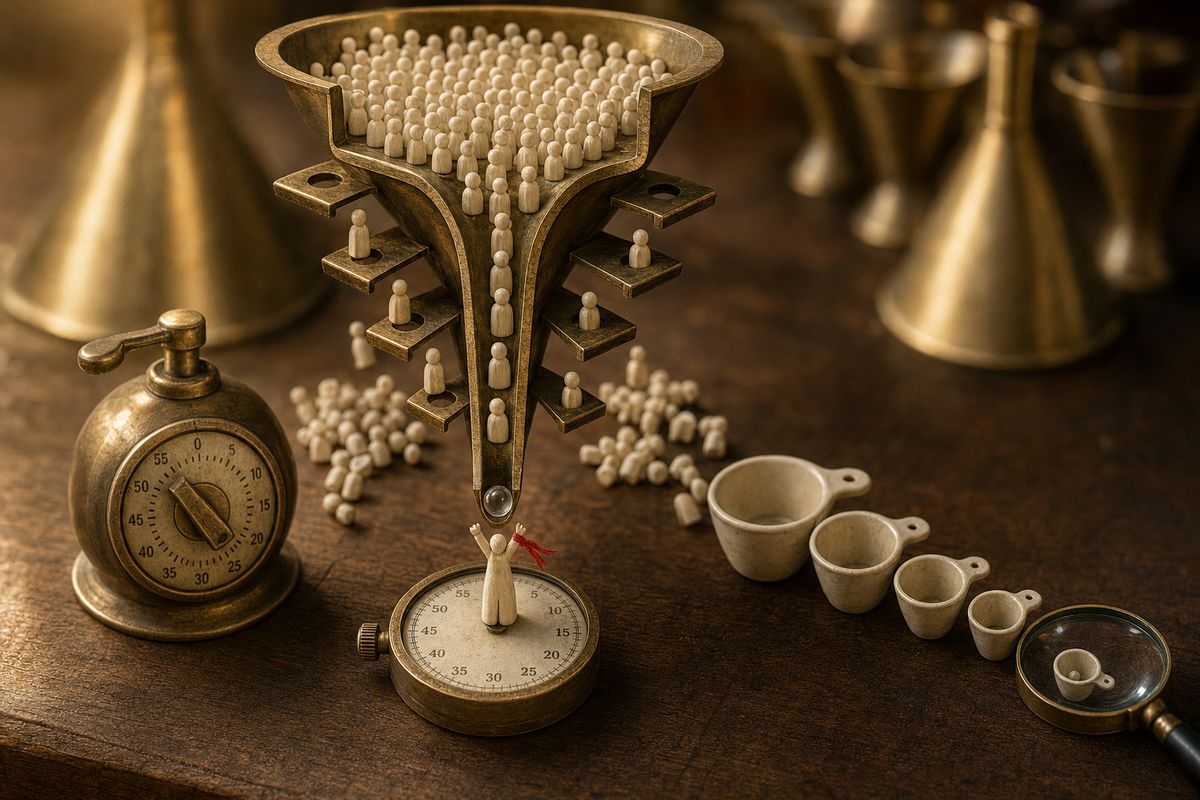
The requester cohort is the set of accounts that asked for the feature, and every adoption figure should state which stage of that cohort it is measured against. This is cohort analysis applied to one feature. Each stage is a subset of the one before it.
| Stage | Definition | Question it answers | What a gap here usually means |
|---|---|---|---|
| Eligible | Requesting accounts that should be able to use the feature, given plan, permissions and region | Did we build it for the people who asked? | Scope or packaging excluded some requesters |
| Got access | Accounts where the flag, rollout or plan actually enabled it | Did they receive it? | Flag misconfiguration, plan-gating bug, staged rollout not complete |
| Had an opportunity | Accounts where the relevant job occurred during the observation window | Did they need it yet? | The job is infrequent (month-end, quarterly), or the window is too short |
| Completed the job | Accounts that finished the task using the feature | Did it work for them? | Usability problems, bugs, unaware users, or the feature misses the real need |
| Returned | Accounts that used it again at the next opportunity | Did they choose it over their workaround? | First use disappointed, quality issues, or the old workaround is still easier |
"Had an opportunity" is the denominator most teams skip. If the job didn't occur during the window, as with a month-end close or a quarterly report, non-use is not evidence of rejection.
Keep account-level and user-level counts in separate columns, and never merge them into one percentage. Account counts tell you whether the customer's problem was solved. User counts tell you how widely the feature spread inside each account.
Add one more column: how much change each account was asked to absorb during the observation period. Other releases, a migration or a pricing change can all suppress adoption. An account in the middle of a platform migration may ignore your new export option for reasons that have nothing to do with the export.
Step 3: Put Quality Beside Speed
A faster release that creates weeks of cleanup has not reduced the price of learning. Speed only counts as progress when the thing delivered holds up. Track four quality measures next to your timing data:
- Regressions: existing behavior that broke because of the change.
- Rework: engineering days spent correcting the release after it shipped.
- Support burden: tickets, chats and CSM escalations the feature generated.
- Keep-or-remove cost: the engineering cost of maintaining the experiment, or of removing it cleanly if it fails.
Review reliability and performance alongside the mix of incoming requests. Ask what customers are requesting now. If they are still asking you to fix the existing experience, the feature has added surface area without solving the problem. If they are asking to extend it, with more formats, more filters or scheduling, that is a sign the first version landed.
Ryan Singer's advice in Shape Up, Chapter 11: Get One Piece Done applies here. Build a small, integrated, working slice early so it can be judged on real use. A slice that customers can complete gives you more information than many half-finished tasks, and it tells you sooner whether the quality cost is acceptable.
Step 4: Match Each Claim to the Evidence It Needs
Every claim about a feature needs evidence that can support it, and stronger claims need stronger evidence. Use this ladder:
- A request shows a perceived need. Someone believed the feature would help them.
- Requester adoption is the first test. Did the people who asked complete the job with it?
- Adoption beyond the requesting group shows broader fit. Non-requesters finding and using it suggests the need is wider than the original asks.
- Measurable task improvement shows value. Faster completion, fewer errors or fewer support contacts for the same job.
- Retention or expansion claims require a suitable design and longer observation. These sit at the top of the ladder for a reason.
Be clear about what each observation can and cannot prove. A positive usability session shows that someone understands a control, not that they will come back to it. Repeated use shows adoption, not that the feature caused retention.
Teresa Torres's work on assumption testing fits here. She breaks ideas into desirability, viability, feasibility, usability and ethical assumptions and tests the riskiest first. Post-release measurement is the final assumption test.
Where possible, compare against your own previous approach. Use similar jobs, similar customers, similar release scopes and similar observation windows. Your last comparable release is a better benchmark than any industry figure.
Step 5: Measure Support and Chat Improvements by Outcome Class
When a feature is meant to improve support or chat outcomes, report resolved, partially resolved, unresolved and unclear conversations as separate counts. A single "resolution rate" hides how much work moved between categories.
- Keep the evidence used to classify each conversation: the transcript excerpt, the ticket status or the follow-up, so anyone can audit the call.
- Compare similar requests before and after the change, not all conversations.
- Watch for the same customers needing to ask again. A conversation marked resolved that returns a week later was not resolved.
Red flag: if apparent resolution rises because ambiguous chats were reclassified rather than because more work was completed, the number has improved and the outcome has not. Ron Kohavi's "Twyman's law" applies: any figure that looks interesting or different is usually wrong. Check sudden jumps in resolution, and surprising adoption spikes, before you celebrate them.
Worked Example: An Eight-Requester Feature Report
This is an illustrative example, not BuildBetter data.
Eight accounts requested bulk export of filtered reports. Here is how the five steps play out.
Timing. Request to release took 12 days. Release to notification took 9 days. Notification to first completed job took 3 days. Notification was the slowest interval. Engineering was not the bottleneck.
Cohort at account level: 8 eligible, 6 got access, 4 had an opportunity, 3 completed the job, 2 returned at the next opportunity.
Cohort at user level, reported separately: 11 users at those accounts tried the feature, and 7 completed an export.
The "75 percent adoption" figure. It is 3 of 4 accounts that had an opportunity. Measured against all 8 requesters, it is 3 of 8. The 2 accounts without access represent an access gap, not a rejection.
Quality. 1 regression in scheduled reports, 2 support tickets about file format, and about 2 engineering days of rework.
Beyond the requesters. 5 non-requesting accounts completed an export in the window. This is an early sign of broader fit, not proof of it.
| Section | Result |
|---|---|
| Interval timings | Request → release: 12 days · Release → notification: 9 days · Notification → first completed job: 3 days |
| Denominator ladder (accounts) | 8 eligible → 6 got access → 4 had opportunity → 3 completed → 2 returned |
| Users (separate) | 11 tried · 7 completed an export |
| Quality | 1 regression (scheduled reports) · 2 format tickets · ~2 days rework |
| Claims supported | 3 of 4 accounts with the job completed it; 2 returned; 5 non-requesters also used it |
| Claims not supported | Any retention or expansion effect; broad fit beyond early signal |
| Decision | Keep. Fix plan-gating bug for 2 accounts. Personally notify all 8 requesters. Fix format issue. Re-measure next monthly cycle before any broader rollout claim. |
The report does not claim a retention or expansion effect, because neither the observation window nor the design can support one. The decision follows from the gaps. Access and notification are fixable process problems. The format issue is a product problem. The next read happens on a set date.
What Is a Good Feature Adoption Rate?
There is no universal good feature adoption rate. A rate only means something once its denominator and the job's expected frequency are stated.
- Judge requester adoption against "had an opportunity," not against all customers or all eligible accounts. An account that never hit the job couldn't have adopted the feature.
- Account for frequency. A feature for an occasional but important job, such as annual reporting or a quarterly audit export, can succeed with very low daily usage. Daily active usage would rank it near the bottom even if it saves customers days each year.
- Compare against yourself. Use your own previous releases with similar scope, similar customers and matched observation windows. Industry benchmarks mix products, feature definitions and job frequencies, so they don't transfer well to a single feature.
If you need a single sentence for a stakeholder, use this form: "Of the N requesting accounts that had the job during the window, X completed it with the feature and Y returned at the next opportunity." That sentence is more useful than any percentage on its own.
How to Report Small Numbers Honestly
With small cohorts, report counts first and percentages second, and always name the denominator in the same sentence. A swing of one account can move a percentage by 25 points when the denominator is four.
- Counts first: "3 of 4 accounts," then "(75%)" if you include a percentage at all.
- Denominator in the same sentence: "3 of 4 accounts that had the job," not "75% adoption" with a footnote.
- Accounts and users separately: two lines, never one blended figure.
- State the limits and the next read: "This does not yet support a retention claim. Next read: March 3."
- Publish the awkward results too. The feature nobody used may explain the method better than the feature everyone liked. A team that only reports wins teaches itself nothing about its own judgment.
Small samples are normal in B2B. Eight requesting accounts can be a large share of revenue. Report them plainly, without inflating them into percentages that sound like population statistics.
When a Before-and-After Chart Cannot Prove the Effect
A before-and-after chart alone cannot isolate a feature's effect. Other releases, seasonality, changes in account mix and the change load customers were absorbing all move at the same time as your feature. Any of them can produce the line you see.
Retention and expansion claims need a suitable comparison design and a longer observation window. A support-ticket drop the month after launch could come from your feature, a holiday lull, a large account churning out of the sample, or a docs update the support team shipped the same week.
What to do instead:
- Comparison group: similar accounts that didn't get the feature or didn't request it, observed over the same window.
- Matched observation windows: compare the same weeks of the month or quarter, so cyclical jobs line up.
- Controlled experiment: where you have enough volume, randomize access. Kohavi's Microsoft finding, that roughly one third of ideas improved their target metric, is a reminder of how often intuition alone is wrong.
When none of these are feasible, say so in the report and keep the claim at the level the evidence supports.
Common Mistakes When Measuring Feature Success
Most feature measurement mistakes come from reporting a number without stating what it counts. Watch for these:
- Reporting deploys or merged PRs as customer value.
- Quoting a percentage without its denominator.
- Blending account and user counts into one figure.
- Starting the clock at release instead of at the customer's request.
- Skipping individual requester notification, then reading low uptake as low demand.
- Ignoring regressions, rework and support load.
- Claiming retention from a before-and-after chart.
- Counting reclassified "unclear" chats as resolutions.
- Hiding features that nobody used.
When You Need Tooling (and Which Tools)
The spreadsheet method works well up to about 2 to 3 measured releases a month with requester cohorts under roughly 30 accounts. It stops scaling when requests are scattered across calls, Slack, tickets and surveys, because rebuilding the requester list by hand becomes the bottleneck.
1. BuildBetter — Best for building the requester cohort from scattered feedback
BuildBetter unifies call recordings, Slack, support tickets and survey feedback through 100+ integrations, so each account in the requester cohort can be traced back to the original conversation where it asked. Tracked Objects link requests to evidence and close the loop when you ship, and BuildBetter drafts loop-closure emails so each requester is notified individually. That speeds up Step 1's notification interval. Honest caveat: it is not a product-analytics event tracker, so pair it with one for completion and return events.
2. PostHog — Best for completion and return events
Product analytics and session replay for checking whether users actually completed the job. See the docs on watching recordings.
3. Metabase — Best for building the denominator ladder from your database
An open-source BI tool that can query plan, flag and event tables to build the five stages automatically.
4. A shared spreadsheet — Best for small cohorts
Still the right tool when cohorts are small and releases are infrequent.
FAQ
How do you know if a feature solved the customer's problem?
You know when the requesting accounts that had the job completed it with the feature and returned at the next opportunity. Report each count against its own denominator: eligible, got access, had an opportunity, completed, returned.
What is the difference between feature adoption and feature impact?
Adoption shows that customers use the feature repeatedly. Impact requires a comparison showing that something measurable improved because of the feature, such as task time, error rate, support volume or retention. Adoption is necessary for impact but does not prove it.
How long should you wait before judging a feature?
Wait until the job has occurred at least twice for the requester cohort: once for first completion, once to test return. The job's natural frequency sets that point, not a fixed number of days. A daily task may take a week. A month-end task may take two to three months.
Should you measure accounts or users?
Measure both and report them separately. Account counts answer whether the customer's problem was solved. User counts answer how widely the feature spread inside the account. Never merge them into one percentage.
What is a good feature adoption rate?
There is no universal benchmark. Judge requester adoption against accounts that had an opportunity to do the job, and compare against your own past releases of similar scope and observation window. Low daily usage can be a success for an infrequent but critical job.
Can a before-and-after chart prove a feature reduced churn?
No. Retention claims need a suitable comparison design, such as a matched comparison group or a controlled experiment, plus a longer observation window.
Are deploys a good measure of product progress?
Only of delivery activity. Spencer Shulem writes that pull requests, deployments and customer outcomes should be tracked separately, because only outcomes show customer value.
Sources and Further Reading
- Pendo, The 2019 Feature Adoption Report
- Kohavi et al., Online Controlled Experiments at Large Scale (2013)
- Teresa Torres, Assumption Testing
- Ryan Singer, Shape Up, Chapter 11: Get One Piece Done
- Wikipedia, Cohort analysis
- Josh Seiden, Outcomes Over Output (2019)
- Spencer Shulem, Ship First: How to Build Self-Improving Products
Make Churn Optional
Measuring the answer starts with knowing exactly who asked. BuildBetter connects every call, ticket, Slack thread and survey to the accounts behind them, so your requester cohort, notifications and follow-ups come from the original conversations instead of a hand-built list.
Make churn optional. Book a demo.
Get Ship First
This method comes from Ship First: How to Build Self-Improving Products by Spencer Shulem: 24 short chapters on going from a customer request to a working release. Get the free PDF or EPUB, or read it on Kindle.