How to Measure Product Success: 4 Metrics That Matter (2027)
Measure product success with retention, engagement, expansion and conversion. Formulas, benchmarks, a spreadsheet method and a worked keep/kill quarter.
Your team reports velocity, story points and features shipped every sprint. The burndown chart looks healthy and the release notes are long. Still, nobody in the room can say whether a single customer is better off because of any of it. This guide from the BuildBetter team gives you a method you can run this week with a spreadsheet and no budget. It covers how to measure product success with four customer-outcome metrics and how to tie each number back to the features and named customers behind it.
What Product Success Actually Means
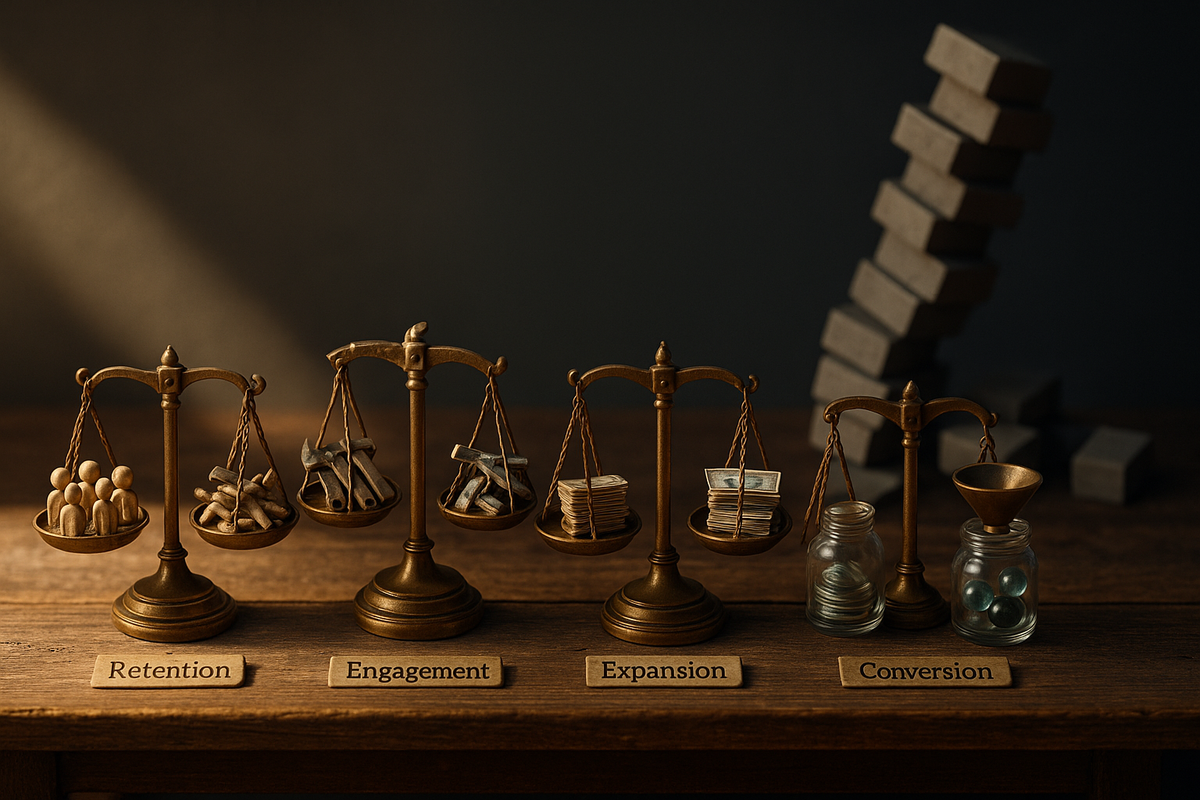
Product success is whether customers stay, use what you built, buy more, and whether prospects become customers. It is measured with four numbers: retention, engagement, expansion and conversion. Features shipped, velocity and story points measure output, not success.
Chapter 4 of Customer-Led Development compresses this into one line: you get what you measure. If you measure features shipped, you get features shipped, and nobody asks whether anyone uses them. It is a close cousin of Goodhart's Law: when a measure becomes a target, it ceases to be a good measure.
Here are the four product success metrics in one line each. Full formulas come in the method section.
- Retention: customers are staying.
- Engagement: customers are using the product.
- Expansion: customers are buying more.
- Conversion: prospects are becoming customers.
This page gives you:
- Exact definitions and formulas, with benchmarks
- A three-tab spreadsheet method you can start today
- One worked quarter, including a feature that got killed
- The common mistakes
- The point where a spreadsheet stops being enough
Why Most Teams Measure the Wrong Things
Most product teams measure output because output is easy to count, and the cost of that choice is a backlog of features nobody uses. The term "feature factory," popularized by John Cutler in 2016, describes teams that celebrate shipping and never check impact.
The feature factory
The numbers cited in Customer-Led Development, chapter 4, are stark:
- 80% of features are rarely or never used.
- Only 12% of features generate 80% of product usage, a sharper skew than the classic Pareto split.
- Public cloud companies collectively spent up to $29.5 billion building features that go unused.
- A $50M-revenue company might waste an estimated $8.4M a year on features customers never touch.
Incentives, not incompetence
Teams optimize whatever they are measured on. Each output metric produces a predictable behavior:
- PMs measured on features shipped ship features.
- Teams measured on velocity optimize cycle time and throughput, not direction.
- Engineers measured on code output grow the codebase, and maintenance cost grows with it.
- Sales measured on deals closed promise whatever closes the deal, including roadmap items that feed the factory.
What breaks in practice
- Averages hide named customers. "24% adoption" tells you nothing about whether the accounts that asked for the feature use it.
- Requests are scattered. Feature requests live in calls, Slack and tickets, so nobody can link a shipped feature back to its requesters.
- OKRs compete. Each department has its own objective, and they pull against each other.
- Subscription revenue masks non-use. Customers can stay subscribed without using the product. The book calls this delayed churn.
The vanity metrics graveyard
| Metric | What it measures | The problem |
|---|---|---|
| Features shipped | Output | Says nothing about outcomes |
| Story points / velocity | Speed | Says nothing about direction |
| Lines of code | Activity | Says nothing about value |
| NPS alone | Sentiment | Sentiment is not behavior |
| DAU/MAU without context | Visits | High DAU with high churn is delayed failure |
The fix is to replace output metrics with four customer-outcome metrics and tie each one to the features and named customers behind it.
The Method: Measure the Four Metrics and Tie Them to Features and Customers
The method is a product metrics framework built on retention, engagement, expansion and conversion, with every shipped feature linked to the customers who asked for it. It comes from chapter 4 of Customer-Led Development: How to Build What Your Customers Want When AI Can Build Anything by Spencer Shulem. Everything below runs on a spreadsheet.
The four metrics at a glance
| Metric | Question it answers | Formula | Benchmark | Owning department |
|---|---|---|---|---|
| Retention | Are customers staying? | Gross revenue retention (GRR) = (starting ARR − churned ARR − downgrade ARR) ÷ starting ARR | Private B2B SaaS median 91%, top quartile 95%. Benchmarkit's 2026 data puts the median lower, at 84%. | Product |
| Engagement | Are they using it? | Activation rate = new accounts reaching the defined first-value action ÷ new accounts. Core feature adoption = active accounts using the core feature in the period ÷ active accounts | 37.5% average activation; 24.5% average core feature adoption (Userpilot, as cited in the book) | Marketing |
| Expansion | Are they buying more? | Net revenue retention (NRR) = (starting ARR + expansion − churn − downgrades) ÷ starting ARR | Median near 101% in private SaaS surveys; 110% among public companies that report it | Customer Success |
| Conversion | Are prospects becoming customers? | Trials, freemium accounts or PQLs that become paid ÷ total in the cohort | PQLs 8–15%, free trials 18–30%, freemium 5–8%, traditional leads 2.8–3.5%. PQLs convert at 2.8x traditional leads. | Sales |
Two calculation notes. GRR excludes expansion, so it can never exceed 100%. NRR (also called net dollar retention) can. Both must be computed on a fixed cohort of customers who existed at period start. Including revenue from customers acquired during the period is the most common NRR error.
Step 1: Write the definitions down before you count anything
Decide the following and freeze it for the year:
- Revenue or logo retention. Logo retention counts customers; revenue retention counts dollars. Losing many small accounts hurts logo retention but barely moves GRR. Pick one as primary.
- The activation action. Make it specific and observable, such as "imported first dataset and invited one teammate within 14 days." "Logged in" does not count.
- Which feature counts as core.
- The conversion cohort window, for example 30 days from trial start.
Changing definitions mid-year turns trend lines into noise and invites gaming.
Step 2: Build three spreadsheet tabs
- Accounts tab: one row per customer. Columns: ARR at period start and end, churn flag, downgrade flag and amount, expansion amount, activated flag, core-feature-active flag.
- Features tab: one row per shipped feature. Columns: ship date, named customers who requested it, requesters who adopted it, overall adoption %, and what has happened since to those requesters' renewal and expansion.
- Snapshot tab: the four numbers each month, calculated from the Accounts tab.
Step 3: Tag requesters when a feature enters the roadmap
Add the names of the customers who asked for a feature at the moment it enters the roadmap, not after it ships. Pull names from call notes, tickets and sales requests. Tagging after the fact means reconstructing from memory, which biases the list toward the loudest accounts. The book's rule: track feature adoption by requester. Did the customers who asked for it use it?
Step 4: Measure time-to-value, not time-to-ship
Record the date each requesting customer first used the feature, not the date the code merged. A feature that shipped in two weeks and sat unused for three months has a time-to-value of three and a half months.
Step 5: Assign one primary metric per department
- Product: primary retention; reinforcing engagement and conversion.
- Customer Success: primary expansion; reinforcing retention.
- Sales: primary conversion; reinforcing retention.
- Marketing: primary engagement; reinforcing conversion.
Because the metrics overlap, no department can improve its own number at another department's expense. A sales team that closes poor-fit deals hurts the retention number it shares with product.
Step 6: Set the review cadence
The book does not prescribe a calendar, so here is a proposed rhythm:
- Monthly: refresh the Snapshot tab and read the four numbers against last month and the benchmark.
- Quarterly: run a keep/kill review of every feature shipped in the prior two quarters, using requester adoption and overall adoption.
- Each review cycle: PM performance reviews use owned-feature retention, engagement and expansion, plus the named customers whose requests were addressed.
Step 7: Make the keep/kill rule explicit before the review
Write the rule down before anyone sees the data. Example: if fewer than half of the named requesters use a feature within one quarter of shipping, and overall adoption is below the core-feature baseline, it is a kill candidate. The book's framing: ship to the customers who asked, keep what they use, delete the rest.
Step 8: Rewrite the roadmap as outcomes
- Before: "Q1: build features A, B, C."
- After: "Q1: improve retention for Segment X by 5 points. Q2: raise Feature A adoption to 60%."
Why the four metrics reinforce each other. Engagement predicts retention. Retention lifts NRR. Five percent monthly churn means losing 46% of customers a year. A fixed customer base compounding at 120% NRR grows 2.5x in five years, while one at 90% shrinks by about 40%.
Worked Example: One Quarter's Dashboard for a B2B Product
This is an illustrative scenario, not a customer case study. It describes a hypothetical B2B SaaS company with 120 accounts and $2.4M in starting ARR, run entirely from the three-tab spreadsheet above.
The quarter's four numbers
| Metric | Result | Calculation | Versus benchmark |
|---|---|---|---|
| Retention (GRR) | 92% | $2.4M − $120K churn − $72K downgrades = $2.208M ÷ $2.4M | Above the 91% median, below the 95% top quartile |
| Expansion (NRR) | 104% | $2.208M + $288K expansion = $2.496M ÷ $2.4M | Above the ~101% private median |
| Engagement | 41% activation; 28% core feature adoption | From Accounts tab flags | Above 37.5% and 24.5% averages |
| Conversion | 21% trial-to-paid | Trial cohort, 30-day window | Lower half of the 18–30% range |
What moved retention and expansion
A bulk-import feature, requested by 9 named accounts, drove most of the movement. Seven of the nine used it within 30 days. Five of those seven expanded seats, contributing roughly $130K of the $288K in expansion. Overall adoption across all accounts reached 34%, above the core-feature baseline.
The Features tab makes this traceable to names. The row lists the nine requesters, marks the seven adopters with their first-use dates, and links to the five expansion amounts in the Accounts tab. Anyone can audit it.
What did not move anything
A custom dashboard builder was requested by 3 named accounts. One requester used it. Overall adoption was 6%, against the 28% core-feature baseline. It was still generating support tickets and eating maintenance time.
The decision: kill the dashboard builder
| Feature | Requesters | Requesters adopted | Overall adoption | Step 7 rule | Decision |
|---|---|---|---|---|---|
| Bulk import | 9 | 7 (78%) | 34% | Passes both tests | Keep |
| Custom dashboard builder | 3 | 1 (33%) | 6% | Fails both: under half of requesters, under 28% baseline | Kill |
The PM messages the one active requester with an export alternative and a removal date. The engineering capacity moves to the onboarding step that is blocking activation.
What churn revealed
The $120K in churn came from 4 accounts. Three of them had never activated. The root cause was an engagement problem that showed up as a retention problem. That finding sets next quarter's outcome goal: raise activation from 41% to 45%.
The PM review, written the new way
- Retention for owned features: target 0 churn among bulk-import requesters; result 0 of 9 churned.
- Engagement: target 60% requester adoption within 30 days; result 78% for bulk import, 33% for dashboard builder (killed).
- Expansion from feature adoption: target $100K; result about $130K from five named accounts.
- Named customers whose requests were addressed: nine bulk-import requesters, listed by name; one dashboard requester moved to an export workflow.
The old review would have read: "Shipped 14 features ✓."
Common Mistakes When Measuring Product Success
Most measurement failures come from reporting numbers that cannot change a decision. Watch for these:
- Reporting the four numbers without the names behind them. "18% expansion" does not tell you which customers or features drove it, so it cannot change a roadmap.
- Using NPS or DAU/MAU as the success metric. Sentiment is not behavior, and visits are not value. Use them as diagnostics underneath the four metrics, never instead of them.
- Treating engagement as optional because customers still pay. Subscribed but inactive accounts are delayed churn. In the worked example, the non-activated accounts were the ones that churned.
- Giving each department a different north star. The book identifies this as what sank "product-led" at most companies: product was told to lead while sales, CS and marketing kept optimizing their own numbers.
- Counting price increases or forced upgrades as expansion. NRR goes up while customer value does not. Separate voluntary expansion from repricing in the Accounts tab.
- Claiming causation from correlation. Check requester adoption first, and look for other changes in the same accounts, such as a new champion or a pricing change.
- Never killing anything. A quarterly review with no kills is a reporting ritual. Ask the book's question: would you rather ship 50 features with 20% adoption or 10 with 80%?
- Expecting software to fix leadership problems. Comp plans that reward only sales, OKRs that put departments in conflict, pricing that removes the daily incentive to care about usage, and dirty billing data all need a leadership decision. No tool fixes them, including ours.
When a Spreadsheet Stops Working
A spreadsheet tracks the four numbers fine at almost any company size. Retention, NRR, activation and conversion come from billing and product data, and a monthly export covers them.
Manual work breaks on the Features tab: tying each feature to the named customers who asked for it. Requests are scattered across call recordings, Slack threads, support tickets and CRM notes. A practical threshold is roughly 200 pieces of customer feedback a month or more than about 30 shipped features a quarter. Past that, one person can no longer reliably trace who asked for what, and the tab goes stale.
Signs you have hit the threshold:
- Requester columns are blank for recent features.
- PMs reconstruct requesters from memory before reviews.
- The keep/kill review gets skipped because building the data takes days.
| Tool | Best for | Requester linking | Weakness |
|---|---|---|---|
| BuildBetter | Teams past the feedback threshold | Automatic, from calls, Slack, tickets, surveys, CRM | Not a billing system; compute GRR/NRR from billing data |
| Shared spreadsheet | Under the threshold | Manual | Tagging decays |
| Airtable | Structured linked records | Manual entry | Someone still types requests in |
| Coda | Metrics doc and review notes in one place | Manual entry | Same manual-entry problem |
1. BuildBetter — Best for Linking Feature Requests to Named Customers
BuildBetter fills the "who asked for this" column automatically. It brings internal customer voice (call recordings, Slack threads) together with external feedback (support tickets, surveys, CRM notes) through 100+ integrations, including Zoom, Slack, Jira, Salesforce, Zendesk, HubSpot and Intercom. Each request is linked to a named account, with severity and business impact attached.
- Tracked Objects follows requests and commitments and links them to evidence, then closes the loop when you ship.
- Tickets creates Linear and Jira issues with the requesters attached, so tagging happens when work enters the roadmap.
- Documents turns findings into PRDs, and loop-closure emails tell requesters the feature is live.
Pricing is usage-based with unlimited seats. The honest caveat: BuildBetter is not a billing or revenue-analytics system, so you still compute GRR and NRR from billing data. It is also not the deepest option for enterprise survey distribution or dedicated research-repository workflows.
Other Options for Smaller Feedback Volumes
2. A shared spreadsheet
The right choice under the threshold. It is free and transparent, and everyone can see the formulas. Requester tagging is manual and decays over time.
3. Airtable
A good step up for structured linking. Use linked records between Accounts and Features tables, with a view per PM. Someone still has to enter requests by hand.
4. Coda
Suits teams that want the metrics doc, keep/kill notes and formulas in one living document. It has the same manual-entry problem as Airtable.
Decision rule: if your four numbers are trustworthy but your requester column is empty, you need capture and linking, not another dashboard.
FAQ: Measuring Product Success
What are the four metrics for measuring product success?
Retention (are customers staying), engagement (are they using it), expansion (are they buying more) and conversion (are prospects becoming customers). Customer-Led Development argues these four replace features shipped, velocity and story points.
Which product success metric matters most?
Retention. If customers leave, nothing else compounds. Five percent monthly churn means losing about 46% of customers a year.
What is a good retention rate for B2B SaaS?
Private B2B SaaS median gross revenue retention is about 91%, and the top quartile reaches about 95%. Some 2026 datasets (Benchmarkit) put the median nearer 84%, depending on sample mix. Use 95% as the bar to aim for.
What is the difference between gross revenue retention and net revenue retention?
GRR counts only revenue lost to churn and downgrades, so it caps at 100%. NRR adds expansion from existing customers, so it can exceed 100%. Medians are about 101% for private SaaS and about 110% for public companies that report it.
How do you tie product metrics to specific features?
Record the named customers who requested each feature before it ships. Then track whether those customers adopted it, how fast (time-to-value), and whether they renewed and expanded. Feature adoption by requester is the link between output and outcome.
How often should you review product success metrics?
Refresh the four numbers monthly and run a keep/kill review of recently shipped features every quarter. Base PM performance reviews on owned-feature outcomes and named customers served, not features shipped.
Sources and Further Reading
- Spencer Shulem, Customer-Led Development: How to Build What Your Customers Want When AI Can Build Anything, chapter 4, "You get what you measure." Source of the framework and benchmark figures on this page.
- Churn rate (Wikipedia)
- Customer retention (Wikipedia)
- Pareto principle (Wikipedia): background for the finding that 12% of features drive 80% of usage.
- BuildBetter
Make Churn Optional
The four numbers tell you whether customers are better off. The names behind them tell you what to build, keep and kill next. BuildBetter captures every call, ticket and Slack thread, links each request to the account that made it, and tells those customers when you ship.
Make churn optional. Book a demo.
Further reading: Customer-Led Development
The method on this page comes from Customer-Led Development: How to Build What Your Customers Want When AI Can Build Anything by Spencer Shulem, BuildBetter's founder, drawn from more than 2,000 conversations with product leaders. It lays out the full system: how customer truth flows through a company, how every feature traces to a named customer, and how loops get closed.
Start with the overview: What is customer-led development?