How to Detect Emerging Customer Issues Across Calls and Tickets
A six-step early-warning method: one taxonomy, per-theme baselines, smart alerts, quote review, owner routing and fix confirmation. Plus false alarms.
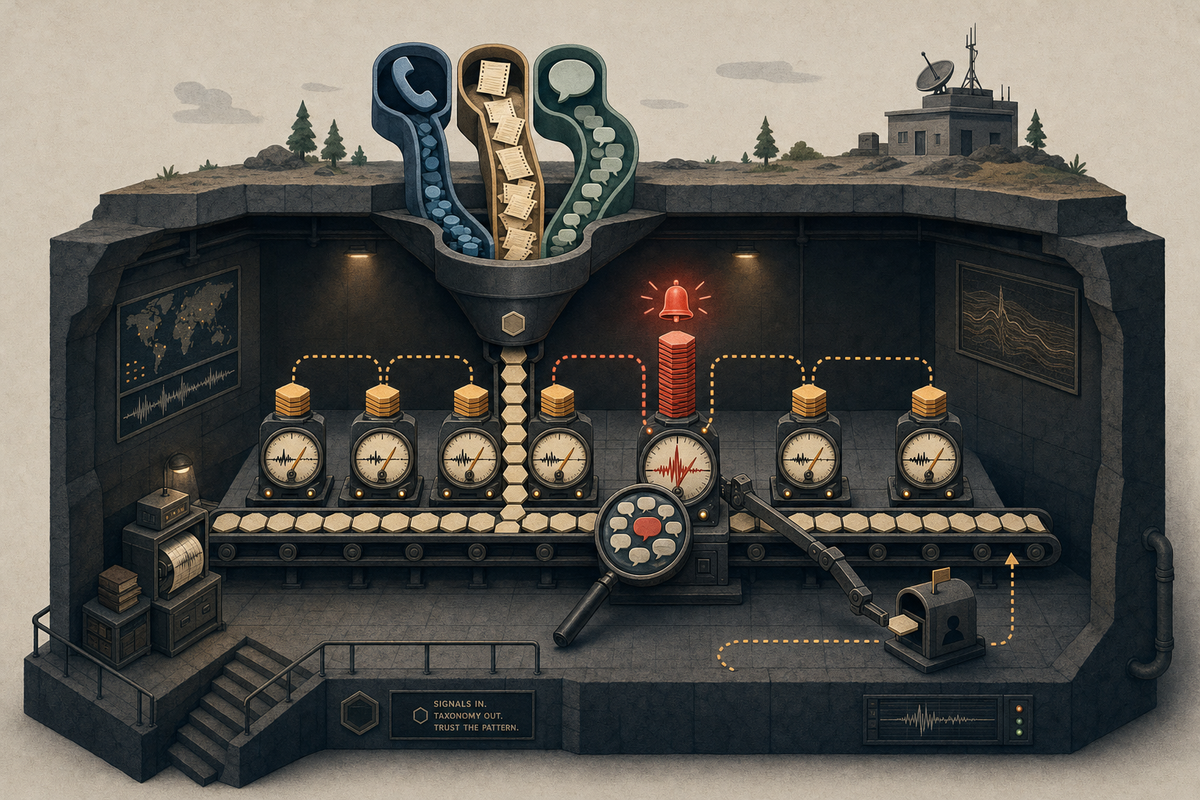
To detect emerging customer issues across calls and tickets, follow six steps. Put every channel under one shared taxonomy. Baseline normal weekly volume for each theme. Alert on two things only: themes that are brand new and week-over-week jumps that clear both a relative and an absolute threshold. Read the underlying quotes before anyone acts. Route each confirmed issue to a named owner. Keep watching until volume returns to baseline after the fix. This works in a spreadsheet, a BI tool, or a feedback platform like BuildBetter. Most of the effort goes into choosing thresholds, filtering out false alarms, and closing the loop.
This guide walks through each step as of November 2026. It includes a hypothetical worked example, a table for telling real issues apart from noise, and answers to common questions.
Why emerging issues get missed
Emerging issues get missed because each channel shows only a slice of the problem, and no single slice looks alarming. Here is a typical pattern. A support agent sees four tickets about a failed export. A customer success manager hears the same complaint on two calls. A product manager notices one frustrated chat. Each person treats it as background noise. Added together, it is a new problem that did not exist last week.
The second reason is that most teams label each channel differently. Support tags tickets by queue or macro. Sales and success notes use free text. Chat might not be tagged at all. When the labels don't line up, you can't add the counts, so you can't see a spike. Sales calls have a related problem: feedback often vanishes after the call ends. We cover that in what happens to customer feedback after a sales call.
Step 1: Use one taxonomy across calls, tickets and chat
The foundation is one shared taxonomy that every channel maps into. A "login failure" from a ticket and a "can't sign in" remark from a call must land in the same bucket. Without that, every later step breaks: baselines, alerts and routing.
Keep the taxonomy shallow and stable. A hierarchy with three or four levels works for most teams, such as product area, feature, and a specific theme or tag. Deep trees spread volume so thin that no single node ever looks unusual. Trees that change every month wreck your baselines.
What a usable taxonomy needs
- Mutually exclusive leaves where possible. If "billing error" and "invoice wrong" are separate tags, merge them or define the boundary in writing.
- A signal type alongside the topic. "Export" as a topic covers bugs, feature requests and confusion. Tag the type (bug, complaint, question, request) separately, so a jump in export bugs doesn't get buried under steady export requests.
- An "unclassified" bucket you actually review. New issues often show up here first, because nobody has created a label for them yet.
- Account and segment metadata. You need to know which customer raised each item, so you can count distinct accounts and not just raw mentions.
- A change log. When you rename, split or merge a theme, record the date. Otherwise a taxonomy edit will look like a volume spike.
If your feedback is currently scattered across Slack, support tools and surveys, centralize it first. Our guide on consolidating customer feedback from Slack, support and surveys covers that groundwork.
Step 2: Baseline normal volume for every theme
A baseline is a theme's normal weekly volume over a trailing window. You need one per theme, because "40 mentions this week" means nothing until you know whether the usual figure is 5 or 50.
A practical starting point:
- Pick a unit. Track two counts per theme: total mentions and distinct accounts. Distinct accounts is the more reliable early-warning number, because it resists one customer filing ten tickets.
- Pick a window. A trailing six to eight weeks is long enough to smooth out random weeks. It is also short enough to reflect your current product.
- Use the median, not the mean. One past incident week can inflate an average for months. The median ignores it.
- Record the normal range. Note the lowest and highest weeks in the window, or a simple spread measure. A theme that swings between 2 and 20 needs a different threshold than one that sits steadily at 10.
- Normalize for overall volume. If total tickets doubled because you onboarded a large cohort, every theme will rise. Track each theme's share of total feedback next to its raw count.
- Baseline per channel too. A theme that normally comes only through tickets and suddenly appears on calls is worth noticing, even if the combined count barely moves.
Themes with very low volume, such as one or two mentions a week, don't support percentage-based alerts. For those, rely on the new-theme and absolute-count rules in the next step.
Step 3: Alert on new themes and week-over-week jumps
Alert on two patterns: themes that appear for the first time, and existing themes whose weekly volume jumps well above baseline. Everything else goes into a weekly review, not an alert. Too many alerts teach people to ignore them.
Rule A: New theme
Fire when a theme with no prior history crosses a small minimum, such as three distinct accounts within seven days. Requiring several accounts filters out one-off oddities. A cluster of similar new complaints from unrelated customers is one of the strongest early signals you can get.
Rule B: Week-over-week jump
Fire when a theme's volume clears both thresholds:
- a relative threshold, for example at least double the baseline median, and
- an absolute threshold, for example at least five more distinct accounts than baseline.
You need both. A relative rule alone fires when a theme goes from 1 to 2. An absolute rule alone misses a quiet theme that quadruples. Tune the numbers to your volume. A team with 200 tickets a week will set lower absolute thresholds than one with 20,000.
Rule C: Escalators
Optionally, raise priority when a jump also shows one of these: it appears in two or more channels, it carries high severity or strongly negative sentiment, or it involves accounts in a high-value or renewal-stage segment. Showing up in several channels is especially useful. It is much harder for a false alarm to appear in tickets, calls and chat at the same time.
Step 4: Read the quotes before acting
Before anyone opens a bug or pages an engineer, read the actual customer quotes behind the alert. Counts show that something moved. The quotes tell you what moved and whether it is real.
Reading ten to twenty raw items usually takes a few minutes. It answers questions no dashboard can:
- Is it one issue or several? A "login" spike might be half SSO failures and half password-reset emails going to spam. Those need different owners.
- Is the classification right? Automated or manual tagging sometimes pulls in look-alike items. If a third of the quotes are off-topic, the real jump is smaller than it looks.
- What is the customer actually trying to do? The job they were doing points to the likely root cause and the right team.
- How bad is it? "Slightly annoying" and "we can't close our books this month" need different responses, even at the same volume.
- Who is affected? Check whether the accounts share a plan, region, integration, browser or recent upgrade.
Save three or four representative quotes in the alert record. They become the core of the handoff in the next step.
Separating real issues from false alarms
Most false alarms come from four sources: product launches, seasonality, one loud account, and changes to your own data pipeline. Each has a recognizable signature, so you can screen for them before escalating.
| Pattern | What it looks like | How to check | Usual action |
|---|---|---|---|
| Genuine emerging issue | New or rising theme across several unrelated accounts, often in more than one channel | Distinct accounts rise as well as mentions; quotes describe the same failure | Route to an owner now |
| Product launch | Spike in questions and confusion about a feature that just shipped | Spike starts on launch day; quotes ask "how do I" more than "it's broken" | Send to docs, onboarding or the launch team; still screen for real bugs mixed in |
| Seasonality | Predictable rise at month-end, quarter-end, renewals, tax season or holidays | Compare against the same period last year or last quarter | Adjust the baseline for that period instead of alerting every cycle |
| One loud account | High mention count, very few distinct accounts | Count distinct accounts; check whether one customer or one champion drives most items | Handle through the account team; watch whether others follow |
| Pipeline or taxonomy change | Sudden step change across a theme, or a drop elsewhere at the same moment | Check the taxonomy change log and whether a new source was connected or a backfill ran | Fix the data or re-baseline; don't escalate |
Launches
A launch reliably produces a spike in questions. That spike is expected, but it can hide a real regression. Separate signal types: a rise in questions about a new feature is normal, while a rise in bugs about an old feature the launch touched is not. Many teams set a two-week "launch window" tag. Alerts tied to the launched area are reviewed by the launch team instead of firing as incidents.
Seasonality
If your customers run payroll, close books or renew contracts on a calendar, some themes will rise predictably. The fix is a seasonal comparison. Check the current week against the same period in the previous cycle, as well as against the trailing baseline. A theme that rises 50 percent every quarter-end isn't emerging. A theme that rises 200 percent when it usually rises 50 percent might be.
One loud account
A single frustrated customer can generate a dozen tickets, mention the issue on every call, and post in a shared channel. That pain is real, but it is an account problem until other customers report it too. This is why the alert rules count distinct accounts. Keep the account on a watch list. If a second and third unrelated account report the same thing, treat it as a real issue.
Step 5: Route every confirmed issue to one owner
Every confirmed issue needs exactly one named owner who is accountable for resolving it. A shared channel where everyone has seen the problem is not ownership.
Map taxonomy branches to owning teams ahead of time, so routing is a lookup and not a debate. The handoff should include:
- the theme name and where it sits in the taxonomy
- current volume, baseline, and distinct accounts affected
- channels where it appears
- three or four representative quotes with links to the source call or ticket
- affected segments or shared attributes you found while reading
- your read on severity and whether a workaround exists
Give support a short holding response at the same time, so agents stop solving the same problem one ticket at a time.
Step 6: Confirm the fix actually closed the issue
An issue is closed when its theme volume returns to baseline and stays there. Shipping a fix doesn't close it. Many teams skip this step, which is why the same complaints quietly come back.
After the fix ships, keep the theme on a watch list for two to four weeks and check three things:
- Volume and distinct accounts are back within the normal range. A partial drop often means the fix covered one cause but not all of them.
- Nothing has moved next door. Fixes sometimes shift the pain to a neighboring theme, such as a login fix that creates a spike in session timeouts. Look at nearby themes in the taxonomy.
- Customers who reported it confirm it works. Follow up with a sample of affected accounts. Their replies are also good evidence for your post-incident notes.
Only then mark the issue resolved. If volume is still elevated after the watch period, reopen the issue with the same owner.
A hypothetical worked example
This example is hypothetical and shows how the steps fit together. A B2B software company tracks a theme called "Reports > Scheduled export > Export fails." Over the past eight weeks, the median is 3 distinct accounts per week, with a range of 1 to 6.
On Monday, the weekly check shows 14 distinct accounts. That clears both rules: more than double the median, and more than five accounts above baseline. The theme also appears on four customer calls and in two chat conversations, so the escalator fires.
The analyst then screens for false alarms. No launch touched exports. Last year's same week shows no seasonal rise. The 14 accounts are unrelated, so no single loud account is driving it. The taxonomy change log is empty for that branch.
Reading fifteen quotes shows that every failing export uses a date range that crosses a month boundary. Two quotes mention it started "after last Wednesday." The issue goes to the reporting team's lead with the quotes, counts and the month-boundary pattern. Support gets a workaround: split the export into two ranges.
A fix ships Thursday. Over the next three weeks, the theme returns to 2, 3 and 2 accounts. No neighboring theme rises. Follow-ups with five affected accounts confirm their exports work. The issue is closed.
How to run this method in BuildBetter
You can run every step above by hand. A platform mainly cuts down the manual tagging and counting. In BuildBetter, signals are extracted from calls, tickets, surveys, emails and Slack messages. According to the Signals page, they are auto-labeled to your own taxonomy across four levels: Domain, Product, Feature and Tag. That covers Step 1. The same page describes 35+ signal types, severity and sentiment scores from -10 to +10, and filtering by Salesforce or HubSpot account fields. These help with the type separation and distinct-account counts described above.
For Steps 2 and 3, the clustering page says themes are grouped by semantic meaning. A cluster forms only from a minimum of 3 similar signals, and the vendor notes best results at 100+ signals. The page also says cluster reports include volume versus the previous period and seasonal patterns. The Signals page describes alerts "when important signals spike or when key accounts mention something critical." It also describes action workflows that push signals to Jira, Linear or Slack, which can support the routing in Step 5.
Ticket and chat data can come in through support platform connections or a feedback ingestion API, per the Tickets and Conversations page. Historical exports can be loaded by CSV, which the CSV and ad hoc upload page lists at up to 100MB per file and 100,000 records per import. Loading history is useful for building baselines and seasonal comparisons. Steps 4 and 6 remain human judgment calls. Even with automated clustering, someone still needs to read the quotes and confirm the fix worked.
Frequently asked questions
How much historical data do I need before alerts are reliable?
Six to eight weeks of consistently tagged data is enough for a usable trailing baseline. For seasonal comparisons, you need at least one full prior cycle, such as last quarter or last year. Until then, treat alerts as prompts for review rather than incidents.
Should I alert daily or weekly?
Weekly works for most teams, because daily counts swing too much for most themes. The exception is severe, high-volume themes such as outages or payment failures. For those, a daily new-theme check with a higher absolute threshold makes sense.
What if my channels can't share a taxonomy yet?
Start with a short list of top-level themes that every channel can map to. Even ten shared buckets let you add counts across channels. Refine the deeper levels later and record each change in the change log so baselines stay honest.
How do I keep one big customer from triggering alerts?
Base alert thresholds on distinct accounts rather than raw mentions. Track mentions separately for context. A big customer's issue still deserves attention, but usually through their account team until other customers report the same thing.
Who should own the early-warning process itself?
Pick one person, often in product operations, support operations or customer insights. They own the taxonomy, the thresholds and the weekly review. The individual issues are routed to the teams that own each product area.
Start with one theme this week
You don't need a perfect system to begin. Pick the five themes that cause the most pain today. Map them across calls, tickets and chat, and write down their baselines. Then run the alert rules by hand for a month, and you'll learn which thresholds fit your volume. If you'd rather not count by hand, see how BuildBetter extracts and clusters signals across your conversations and tickets, and book a demo to try it against your own data.