How to Turn Customer Calls Into Product Insights With AI
An 8-step method for turning customer calls into evidence-backed product insights with AI. Includes an extraction prompt, an insight template, a false-pattern checklist, and a hypothetical worked example.
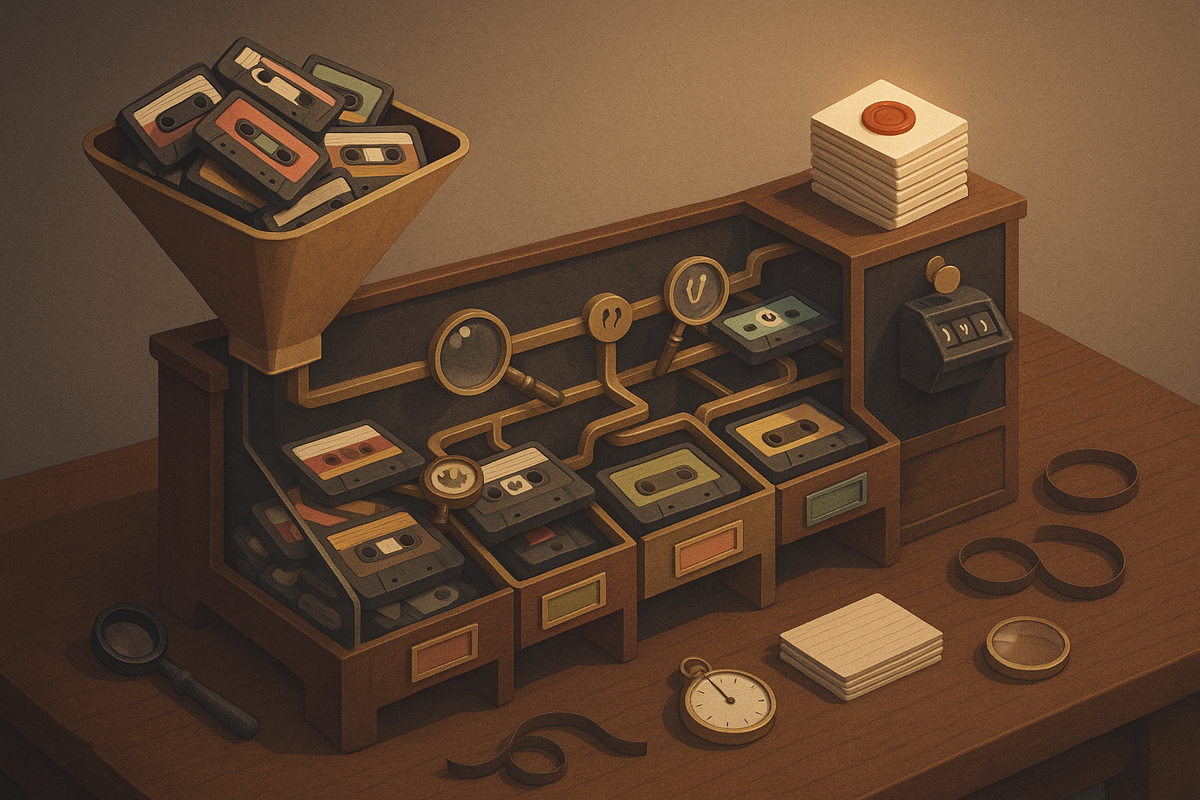
The best way to turn customer calls into product insights with AI is to run every call through one repeatable pipeline. Capture the call with account metadata, extract verbatim quoted signals, and tag them against a single taxonomy. Then cluster them into themes, weight each theme by distinct accounts, write the insight with linked evidence, review it for false patterns, and ship it to the roadmap. You can run this with a spreadsheet and any general-purpose LLM, or in a platform such as BuildBetter once call volume outgrows manual work. AI makes transcription, extraction, and first-pass clustering fast. It does not choose your questions, define your taxonomy, or judge severity. Those stay with your team.
Definition: A product insight is a pattern across many calls. It is counted by distinct account, backed by timestamped verbatim quotes, and tied to a specific product decision. A call summary describes one conversation. An insight changes what you build.
What Separates a Product Insight From a Call Summary
An insight has a count, a denominator, evidence, and a decision. A summary has none of those. “The customer wants better exports” is a summary. “14 of 26 finance accounts rebuild our export by hand at month-end close, and 11 of them call it blocking” is an insight. Those numbers are hypothetical, and they come from the worked example below. The second statement tells you how widespread the problem is, how much it hurts, and which roadmap decision it should inform.
This guide gives you:
- An 8-step workflow that runs on call transcripts, a spreadsheet, and a general-purpose LLM
- A paste-ready extraction prompt and a copy-paste insight template
- A false-pattern review checklist to run before any insight reaches the roadmap
- A hypothetical worked example in which ranking by accounts instead of mentions reverses a roadmap's top item
- Notes on which steps tooling can speed up, and which steps stay human
For a shorter overview of tactics, see 7 ways to transform customer calls into actionable product insights. This page is the step-by-step method behind it.
Why Call Recordings Rarely Change the Roadmap
Call recordings fail to influence decisions because of predictable process breakdowns. Teams rarely lack data. These breakdowns show up most often:
- Nobody watches recordings. Reviewing a call takes at least as long as the call, so the archive goes unopened.
- Recency and proximity bias. PMs give the most weight to the calls they attended and the calls that happened recently.
- Loudness passes for frequency. One champion who raises the same request on five calls looks like five data points. It is one account.
- Call types get mixed. A prospect's sales objection and a churned customer's exit reason both get filed as “feedback,” even though they are evidence for different things.
- Summaries arrive without evidence. “Customer wants better reporting” with no quote and no timestamp cannot be verified or challenged, so engineers discount it.
- Every team tags differently. Sales says “reporting,” support says “exports,” research says “data access.” The same problem gets split into three small themes.
- The loop never closes. The AEs and CSMs who ran the calls never see what happened to what they heard, so they stop flagging things.
Each step below targets one or more of these breakdowns.
The 8-Step Workflow From Customer Calls to Roadmap
The workflow has eight steps: capture, extract, tag, cluster, weight, write, review, and ship. Run steps 2 through 5 weekly or biweekly. Run steps 6 through 8 when a theme is ready for a decision, and at least monthly.
- Capture every relevant call with account, segment, role, date, and call type.
- Extract quoted signals: problems, requests, objections, and outcomes, each with a verbatim quote and timestamp.
- Tag every signal against one shared taxonomy, using a written codebook.
- Cluster tagged signals into themes by meaning, with a human approving each theme.
- Weight themes by distinct accounts, severity, segment, and revenue context.
- Write the insight with evidence, using the template below.
- Review for false patterns before anyone acts.
- Ship to the roadmap as a ticket, brief, or PRD, and report back to call owners.
Step 1. Capture every call with metadata (and decide your questions first)
Before you capture anything, write 2–4 decision questions tied to this quarter's roadmap bets. Good questions are narrow and decision-shaped: “Why do trials stall after week one?” or “What blocks expansion into finance teams?” Signals that don't relate to a current question go to a parking-lot tag. Don't delete them, because next quarter's question may need them.
Then make sure every call produces a transcript with speaker labels and timestamps. Many meeting platforms can export one, depending on your plan and admin settings. Timestamps are what make a quote traceable. Disclose recording on every call and get legal guidance, because consent rules vary by jurisdiction.
Capture this minimum metadata per call: account name, segment or plan, speaker role, date, and call type. If your CRM holds ARR, renewal date, or deal stage, record those too. Without account and segment you cannot weight correctly in Step 5. Call type matters because each type is reliable evidence for different things:
| Call type | Reliable for | Unreliable for | Weight in roadmap decisions |
|---|---|---|---|
| Discovery / research | Real problems and current workflows | Solution design (customers propose, they don't specify) | High for problem definition |
| Sales | Objections and deal-blocking gaps | Predicting usage (prospects over-promise) | High for blockers, low for demand |
| Support | Friction, bugs, severity | Strategic direction | High for severity |
| Churn / exit | Deal-breakers and unmet expectations | Representing the retained base | High for risk; check against the base |
Step 2. Extract quoted signals, not summaries
Extract four non-overlapping signal types from each call:
- Problem: pain in the customer's current workflow (what hurts).
- Request: a solution the customer proposed (what they asked for).
- Objection: a reason not to buy, adopt, or expand (what stops them).
- Outcome: the result they want, or a consequence they described (what success looks like).
One quote can produce two rows, such as a problem and a request. Never merge them into one. Give more weight to specifics about past behavior, current workarounds, and time or money already spent. Give less weight to compliments and hypotheticals such as “I'd probably use that.”
Paste-ready extraction prompt:
You are analyzing a customer call transcript for a product team.
Call type: [discovery/sales/support/churn]. Account: [name]. Segment: [segment].
This quarter's questions: [Q1], [Q2], [Q3].
Taxonomy (use only these tags): [paste codebook tag list].

Extract every instance of:
- PROBLEM (pain in current workflow)
- REQUEST (solution the customer asked for)
- OBJECTION (reason not to buy/adopt/expand)
- OUTCOME (result they want or consequence they described)

For each item return one row:
type | one-sentence paraphrase | verbatim quote (exact words) | timestamp | speaker role | taxonomy tag (or UNTAGGED) | related question (or NONE) | severity (blocking / workaround exists / annoyance / unclear) | raised by (customer / interviewer prompt)

Rules:
- Only use quotes that appear word-for-word in the transcript.
- If no timestamp exists, write NONE.
- Do not infer needs the customer did not state.
- Do not merge separate items.
- Output as a table I can paste into a spreadsheet.
Verification rule: before you trust a batch, spot-check three quotes per call against the transcript. If the model invented or blended a quote, discard that call's output and re-run it in shorter chunks. Details buried in the middle of long transcripts are the easiest to lose, so split long calls into halves. The “raised by” column matters in Step 7, because a topic the interviewer introduced is weaker evidence than one the customer raised unprompted.
Step 3. Tag with one taxonomy across every team
Use one taxonomy for sales, success, support, and research calls. A simple hierarchy works: Product area → Feature → Theme tag, with signal type as a separate field. Keep it in a written codebook. For each tag, record the name, a one-line definition, inclusion and exclusion rules, and one example quote.
Three rules keep the taxonomy usable:
- One named owner approves new tags. Everyone else uses UNTAGGED until the owner decides.
- Paste the codebook into every extraction and clustering prompt, so the LLM reuses existing tags instead of inventing near-duplicates.
- Once a month, have two people independently tag the same five calls. Reconcile the differences and update the definitions.
If calls are only part of your feedback, apply the same taxonomy to tickets, Slack threads, and surveys. Our guide to consolidating customer feedback from Slack, support, and surveys covers that setup.
Step 4. Cluster signals into themes by meaning
Within each taxonomy node, group signals that describe the same underlying problem, even when customers use different words. This is affinity mapping, the core of thematic analysis. An LLM can propose a first-pass grouping. Treat it as a draft, because people construct themes rather than discover them. A named person approves each theme's name and definition.
Don't name a theme from one or two signals. Wait for at least three similar signals; any stricter rule is up to you. Watch for two failure modes. Lumping merges different problems under one broad label, such as “reporting.” Splitting scatters one problem across several small themes. When in doubt, read the quotes side by side and ask whether the same fix would solve all of them.
Step 5. Weight each theme by distinct accounts and severity
Count two numbers per theme: total mentions and distinct accounts. Rank by distinct accounts, never by mentions. Then add context. Which segments and plans are affected? How many accounts rated it blocking versus a workaround or an annoyance? What revenue or renewal timing is attached, where your CRM records it?
Score each theme on frequency (distinct accounts) and severity:
| High severity | Low severity | |
|---|---|---|
| High frequency | Build now | Batch or quick-win fix |
| Low frequency | Investigate (possible segment-specific deal-breaker) | Park |
The “investigate” quadrant deserves follow-up calls before anyone writes a spec. A rare, blocking theme can still matter if it is concentrated in a segment you are trying to win.
Step 6. Write the insight with evidence
Write every insight in the same format, so reviewers can compare them and engineers can check the evidence. Copy this template:
INSIGHT: [Who] [experiences what problem] [with what consequence].
DECISION IT INFORMS: [roadmap item, bet, or question]
EVIDENCE: [X] of [Y] accounts in [segment]; [N] total mentions
SEVERITY: blocking [n] / workaround [n] / annoyance [n]
REVENUE CONTEXT: [ARR, renewal dates, deal stage, if known]
CALL TYPES: discovery [n] / sales [n] / support [n] / churn [n]
QUOTES (3-5):
  - "[verbatim]" - [Account], [role], [call type], [date], [timestamp], [link]
DESIRED OUTCOME: [what success looks like, in the customer's terms]
REQUESTS HEARD: [proposed solutions - inputs, not requirements]
COUNTER-EVIDENCE: [accounts that don't have this problem, or disagree]
CONFIDENCE: high / medium / low, because [reason]
NEXT VALIDATION: [who to call, what to ask]
OWNER + REVIEW DATE: [name], [date]
Requests inform the solution, but the problem and the desired outcome define it. The counter-evidence field is not optional. If you can't find any, say so explicitly.
Step 7. Review for false patterns before anyone acts
Have someone who didn't write the insight run this checklist against it:
- Denominator check: is the account count out of the right base (this segment, this period), or out of everyone you happened to talk to?
- One account, many voices: are three “accounts” actually three people from the same company?
- Champion repetition: does one person drive most of the mentions?
- Prompted, not raised: did the interviewer introduce the topic? Check the “raised by” column.
- Call-type mixing: are prospect objections being counted as customer demand?
- Sampling skew: are you only hearing from engaged champions, and not from end users or silent churners?
- Time clustering: did every mention come from the week after one incident or release?
- Quote integrity: do the quotes appear word-for-word in the transcripts, and do they mean the same thing in context?
- Taxonomy drift: did a broad tag pull in unrelated problems?
An insight that fails a check isn't necessarily wrong. Lower its confidence rating and add a validation step.
Step 8. Ship to the roadmap and close the loop
An insight is done when it reaches the place where work gets planned. For a fix, create a Jira or Linear ticket and paste in the insight, the account count, and two or three linked quotes. For a larger bet, turn the insight into a brief or PRD. Our guide on how to turn customer interviews into a PRD walks through that conversion. Record the affected accounts in Salesforce or HubSpot, so account teams know who is waiting.
Then send AEs, CSMs, and support a short note. Cover what was heard, how many accounts it came from, what is changing, and which customers to follow up with. When the work ships, tell those customers and check whether the problem actually went away.
Worked Example (Hypothetical): 30 Calls, 410 Signals, One Changed Spec
This example shows how account weighting changes a decision. It is a hypothetical composite, not a real customer case. The numbers are invented but internally consistent, so you can follow the math.
Capture. A B2B analytics product sets one quarterly question: “What would make finance teams adopt us as their primary reporting tool?” The team runs 30 discovery calls in a month across 26 distinct accounts, with four accounts having two calls each.
Extract and tag. The extraction prompt produces 410 signals: 160 problems, 120 requests, 75 objections, and 55 outcomes. Spot-checks find six bad quotes, and those calls are re-extracted in shorter chunks. Another 62 signals get the parking-lot tag because they don't relate to the quarterly question.
Cluster and weight. The remaining signals cluster into 18 themes. The theme with the most mentions looks like the winner, until accounts are counted.
| Theme | Mentions | Distinct accounts | Severity profile | Segment | Decision |
|---|---|---|---|---|---|
| Custom dashboard builder | 22 | 5 / 26 | Mostly annoyance | Mixed, mostly enterprise | Investigate |
| Month-end close export reformatting | 17 | 14 / 26 | 11 blocking or heavy workaround | Mostly mid-market finance | Build now (v1) |
Review. The false-pattern check finds that one champion raised the dashboard builder on both of their account's calls, and that interviewers prompted the topic in several calls. The export theme was raised unprompted, came from 14 different companies, and was spread across the month.
Write. The insight, in template form:
Insight: Mid-market finance users rebuild our CSV exports by hand to match their close templates, which costs them most of the first day of month-end close.
Decision it informs: v1 scope for the finance reporting bet.
Evidence: 14 of 26 accounts; 17 mentions. 11 rated blocking or heavy workaround.
— “I lose most of day one of close rebuilding your CSV in our template.” (Account F, 14:32)
— “We export, then someone spends three hours fixing columns before the controller sees it.” (Account K, 22:05)
— “If it came out in our format, I'd stop using the spreadsheet entirely.” (Account R, 31:47)
Desired outcome: A close-ready export with zero manual reformatting.
Counter-evidence: Enterprise accounts mostly use their own BI layer and didn't raise this.
Confidence: High for mid-market; low for enterprise.
Next validation: Collect template samples from the 14 accounts.
Ship. v1 becomes scheduled exports mapped to customer-defined finance templates, tracked as a Linear project with the insight attached. The dashboard builder moves to “investigate” for its five accounts. The PM sends account teams the list of 14 accounts and asks them to book short follow-ups to collect template formats before design starts. Ranking by distinct accounts and severity, instead of by mentions, reversed the roadmap's top item.
Common Process Mistakes That No Tool Fixes
The costliest mistakes are process decisions, not extraction errors. Watch for these:
- Extracting without a question. A list of everything interesting produces no decision.
- Treating feature requests as requirements. Customers describe solutions. You need the problem and the outcome.
- No decision owner. Themes get presented and admired, and nobody is accountable for acting on them.
- Ignoring who you don't talk to. Sampling bias is a research-design problem. Fix it by deliberately scheduling calls with end users and churned accounts.
- Skipping consent. Disclose recording and follow the rules in each jurisdiction where you operate.
- Never closing the loop. When call owners stop seeing results, they stop flagging signals.
Where AI Tooling Helps, and What Stays Human
Tooling helps most with capture, extraction, tagging, clustering, and counting, because those steps repeat on every call. It helps least with choosing questions, judging severity, and the false-pattern review. Signs you have outgrown the spreadsheet:
- Recordings go unreviewed because there are too many of them.
- Sales, CS, and support all run calls, and their tagging doesn't match.
- You need to combine calls with tickets, Slack, or surveys.
- Quotes can no longer be traced back to the recording.
- Answering a new question means re-extracting everything from scratch.
On the Recordings page, BuildBetter describes capturing calls with an optional bot, with BB Recorder for local no-bot recording (a standalone app listed for Mac and iOS), through imports from Zoom, Teams, Meet, and other platforms, or through manual upload. The page also lists support for 37+ languages and custom dictionaries. Its Signals page lists 35+ signal types, severity and sentiment scores from −10 to +10, bias detection, auto-labeling to a Domain/Product/Feature/Tag taxonomy, Salesforce and HubSpot metadata, and workflows that push signals to Jira, Linear, or Slack. The Clustering page says clusters need at least three similar signals to form and generate per-cluster reports. Here is how those vendor-described features map to the manual method:
| Step | In BuildBetter (per its product pages) | Spreadsheet + general-purpose LLM |
|---|---|---|
| 1. Capture | Bot, no-bot local recorder, imports, manual upload, mobile | Export transcripts manually; add metadata by hand |
| 2. Extract | Signals extracted automatically from calls, tickets, Slack, surveys, and more | Run the prompt per call; spot-check quotes |
| 3. Tag | Signals auto-label to your taxonomy | Paste the codebook into prompts; calibrate monthly |
| 4. Cluster | Semantic clustering with a three-signal minimum and per-cluster reports | LLM proposes groupings; a person approves |
| 5. Weight | Filter by CRM account, deal stage, and severity | Pivot table of distinct accounts × severity |
| 6–8. Write, review, ship | Source quotes linked to findings; push to Jira or Linear | Template, checklist, and manual tickets |
Whatever you use, a person still writes the quarterly questions, owns the taxonomy, runs the false-pattern review, and makes the call.
FAQ: Turning Customer Calls Into Product Insights
What is the best way to turn customer calls into product insights with AI?
Capture calls with account metadata, then use AI to extract problems, requests, objections, and outcomes with verbatim quotes and timestamps. Tag those signals against one taxonomy, cluster them into themes, and rank themes by distinct accounts and severity. Write each insight with its evidence, review it for false patterns, and ship it as a ticket or PRD.
What should I extract from a customer call transcript?
Extract problems, requests, objections, and outcomes. Record each one with a verbatim quote, timestamp, speaker role, taxonomy tag, severity, and whether the customer raised it unprompted. With those fields, every insight can be traced back to the exact moment in the call.
Can I use a general-purpose LLM to analyze call transcripts?
Yes, if you give it a strict template and require word-for-word quotes. Spot-check about three quotes per call, split long calls into chunks, and review your plan's data-handling terms before pasting customer data.
How many calls do I need before a pattern is reliable?
There is no universal number. Act when a theme appears across multiple distinct accounts in the same segment, raised unprompted, and survives the false-pattern review. One account repeating itself is not a pattern.
What's the difference between frequency and severity?
Frequency is how many distinct accounts raised a theme. Severity is how much it hurts them: blocking, a costly workaround, or a minor annoyance, ideally with revenue context. Build high-frequency, high-severity themes. Investigate low-frequency, high-severity ones.
How do I avoid acting on false patterns?
Have someone other than the author check the denominator and look for multiple voices from one account, champion repetition, interviewer prompting, call-type mixing, and quote accuracy. Then record counter-evidence and a confidence rating in the insight.
Sources and Further Reading
- Recordings product page (vendor claims on capture, languages, and summaries)
- Signals product page (vendor claims on signal types, scoring, taxonomy, and integrations)
- Clustering product page (vendor claims on cluster formation and reports)
- Product team use cases
- Thematic analysis (Wikipedia)
- Affinity diagram (Wikipedia)
- Product requirements document (Wikipedia)
- Tools to turn customer calls into PRDs
Start With the Calls You Already Have
You can start this week with last month's calls. Write two decision questions, run the extraction prompt on ten transcripts, and fill in one insight template. If the spreadsheet starts to buckle, BuildBetter can run capture, signals, and clustering across calls, tickets, and Slack while keeping every finding linked to its source quote. Book a demo to see it on your own calls.